Shape Reference · Forward Pass
Transformer Shape Trace
Key diagrams only, in order. Every shape transformation from input to output.
← Read the full post
(2, 4) → embed → (2, 4, 4) → +PE → (2, 4, 4) → MHA → (2, 4, 4) → Add&Norm → (2, 4, 4) → FFN → (2, 4, 4)
→ masked MHA → (2, 4, 4) → cross attn → (2, 4, 4) → FFN → (2, 4, 4) → linear → (2, 4, 14) → argmax → (2, 4) d_model=4 · 2 heads · batch=2 · seq_len=4
→ masked MHA → (2, 4, 4) → cross attn → (2, 4, 4) → FFN → (2, 4, 4) → linear → (2, 4, 14) → argmax → (2, 4) d_model=4 · 2 heads · batch=2 · seq_len=4
Input
Token IDs
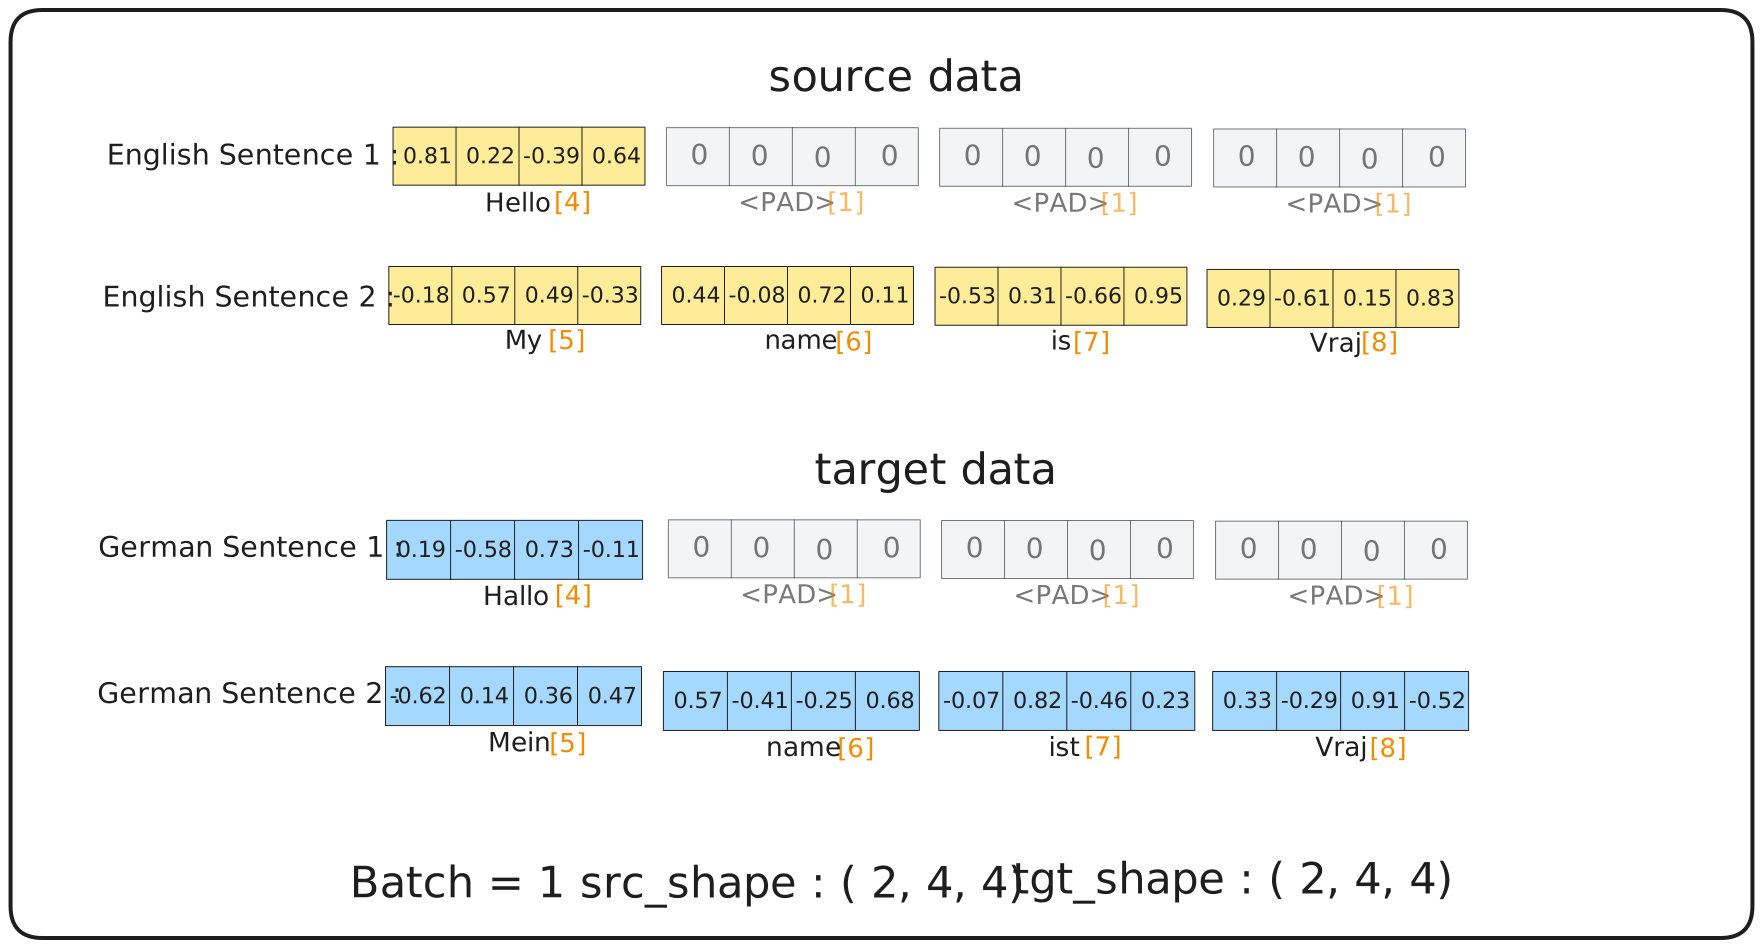
Batch 1 — src & tgt token IDs
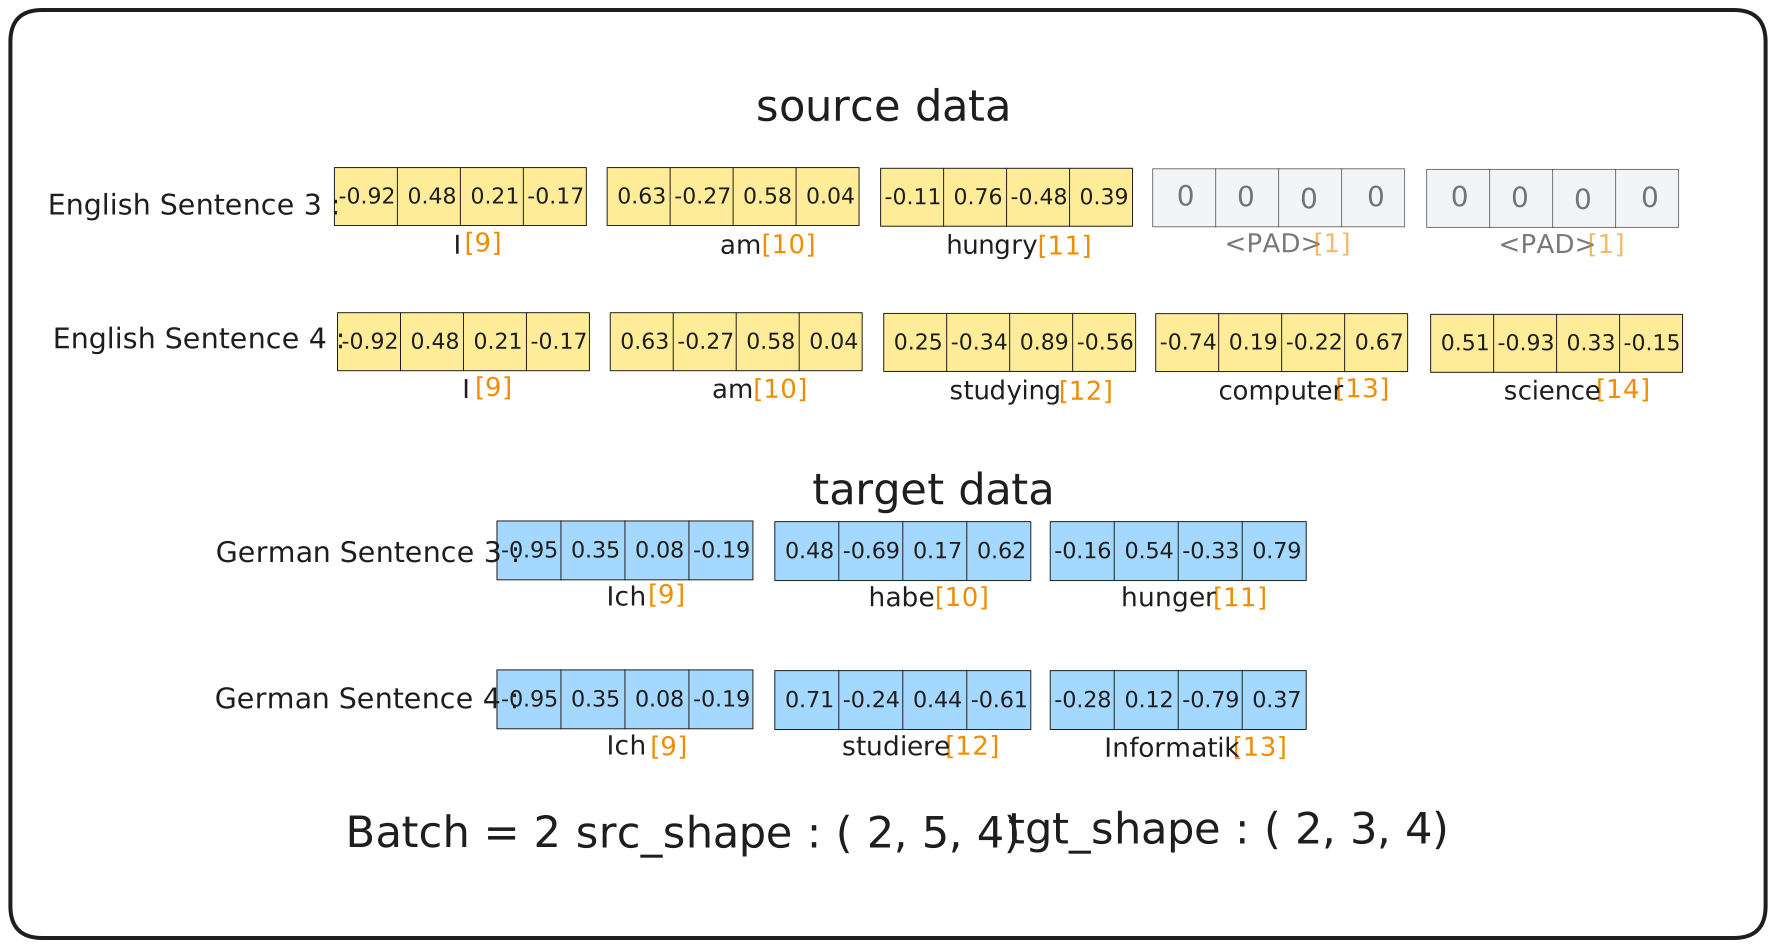
Batch 2 — src & tgt token IDs
embed lookup (2, 4) → (2, 4, 4)
Encoder block — conceptual overview
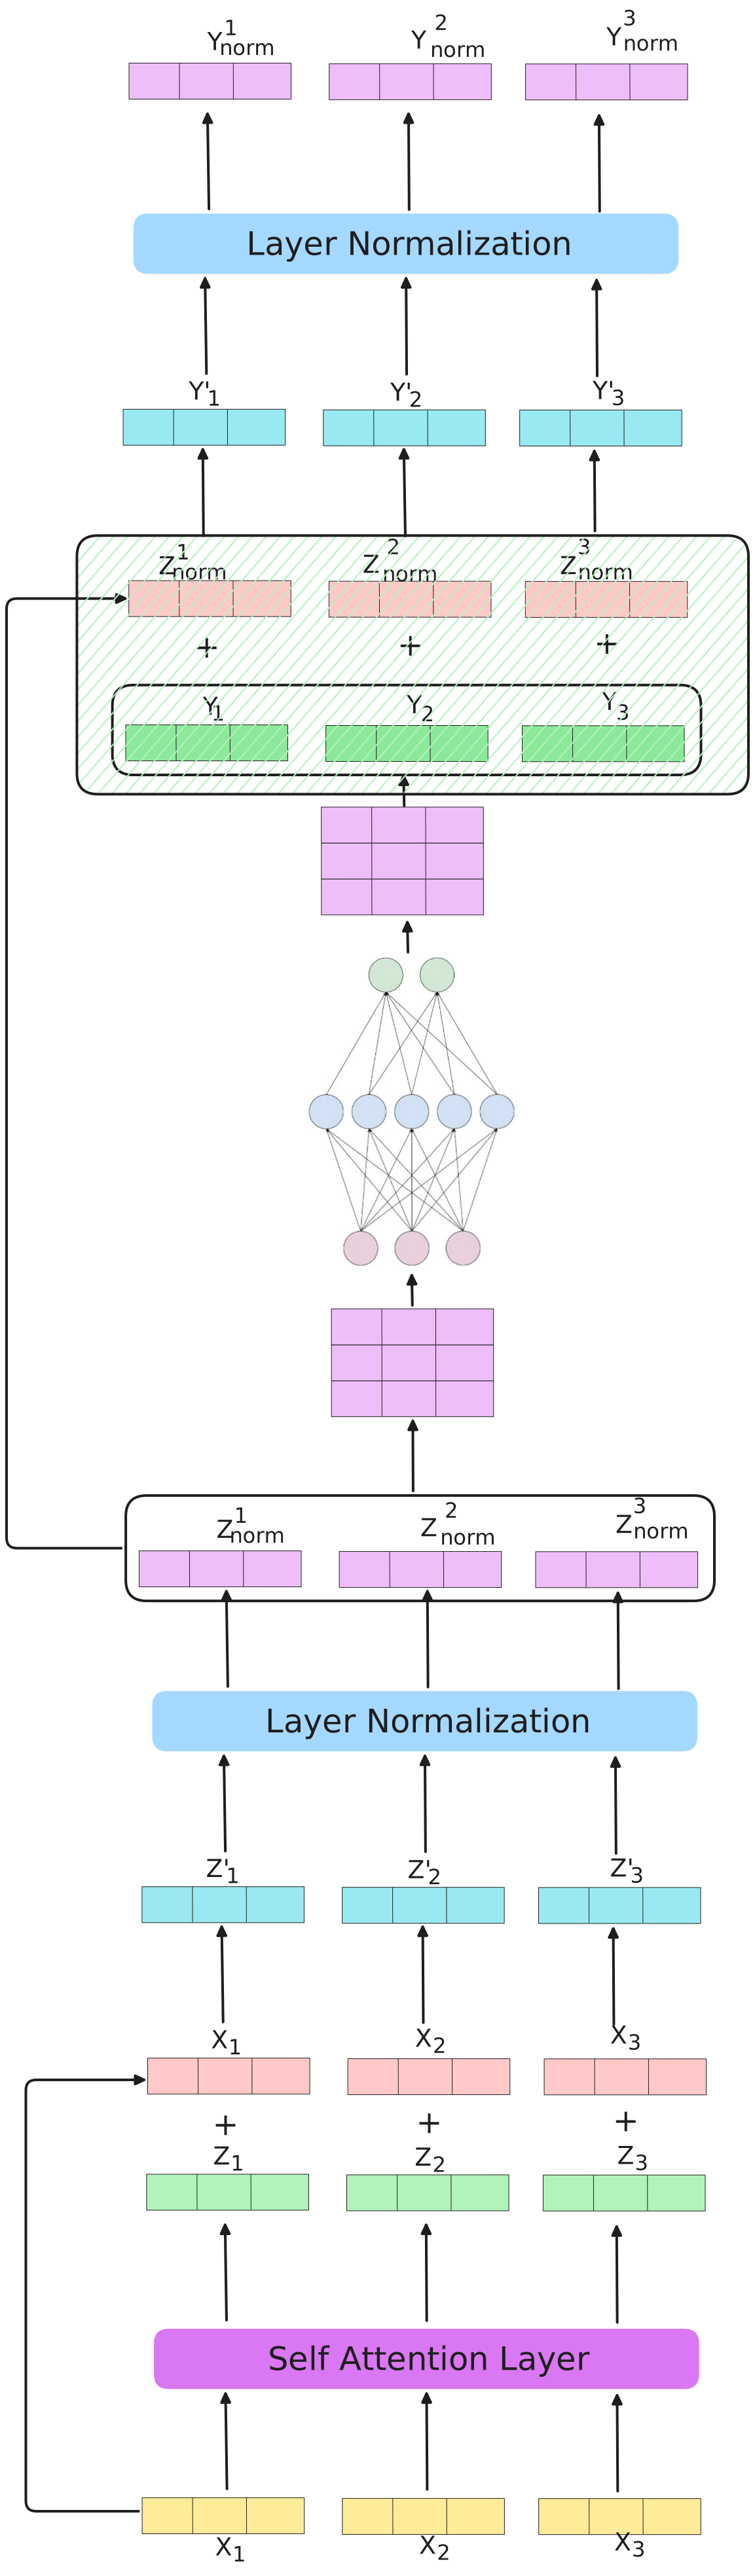
Full encoder: self-attention → Add & Norm → FFN → Add & Norm, repeated N×
02
Embeddings + Positional Encoding
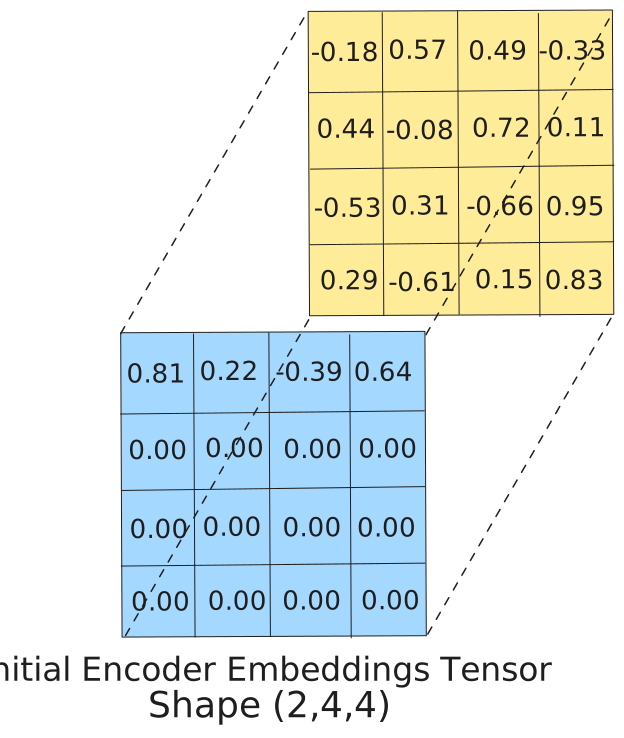
Initial embeddings · (2, 4, 4)
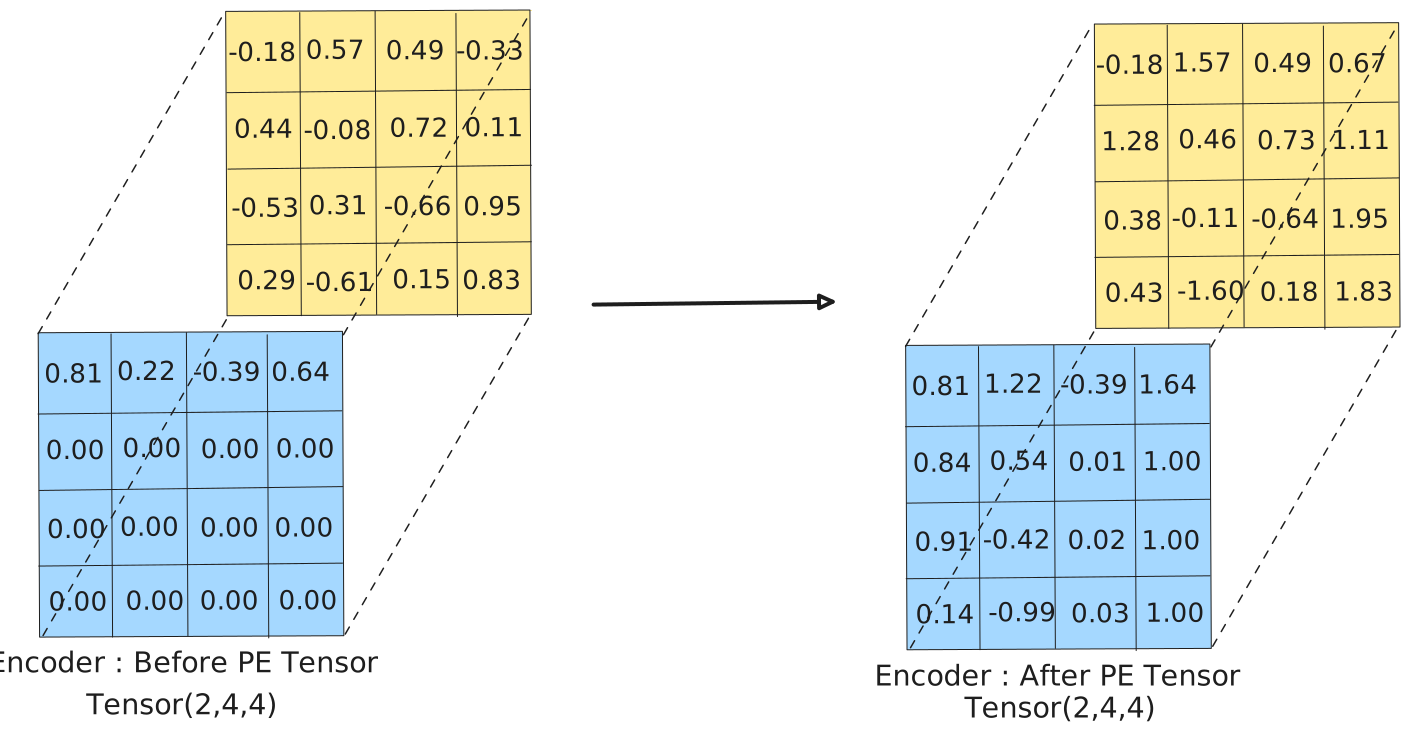
Before & after positional encoding — both batches
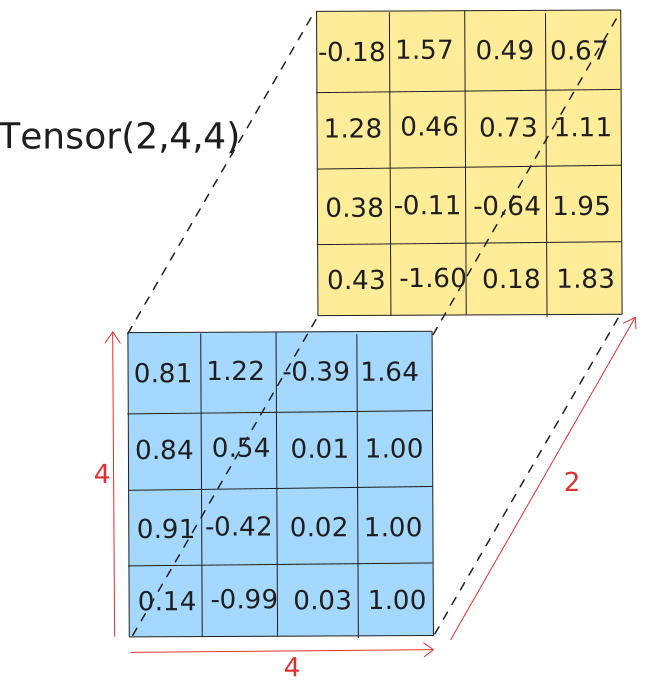
Post-PE encoder input · (2, 4, 4)
project through W_Q, W_K, W_V (2, 4, 4) stays (2, 4, 4)
Q · K · V — conceptual flow
Each token's embedding splits into Q, K, V via learned weight matrices W_Q, W_K, W_V
03
Encoder: Multi-Head Attention
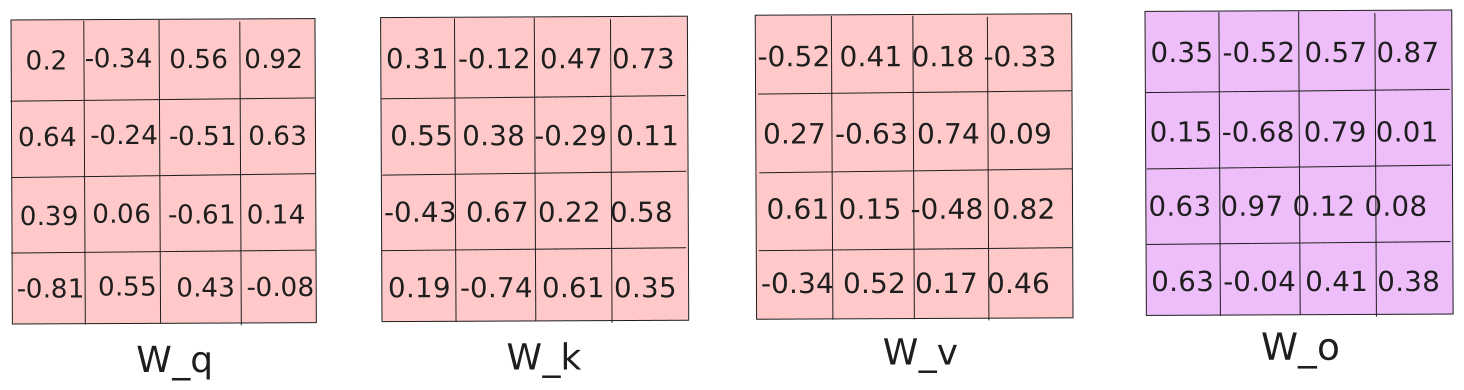
W_Q · W_K · W_V · W_O — four (4, 4) weight matrices
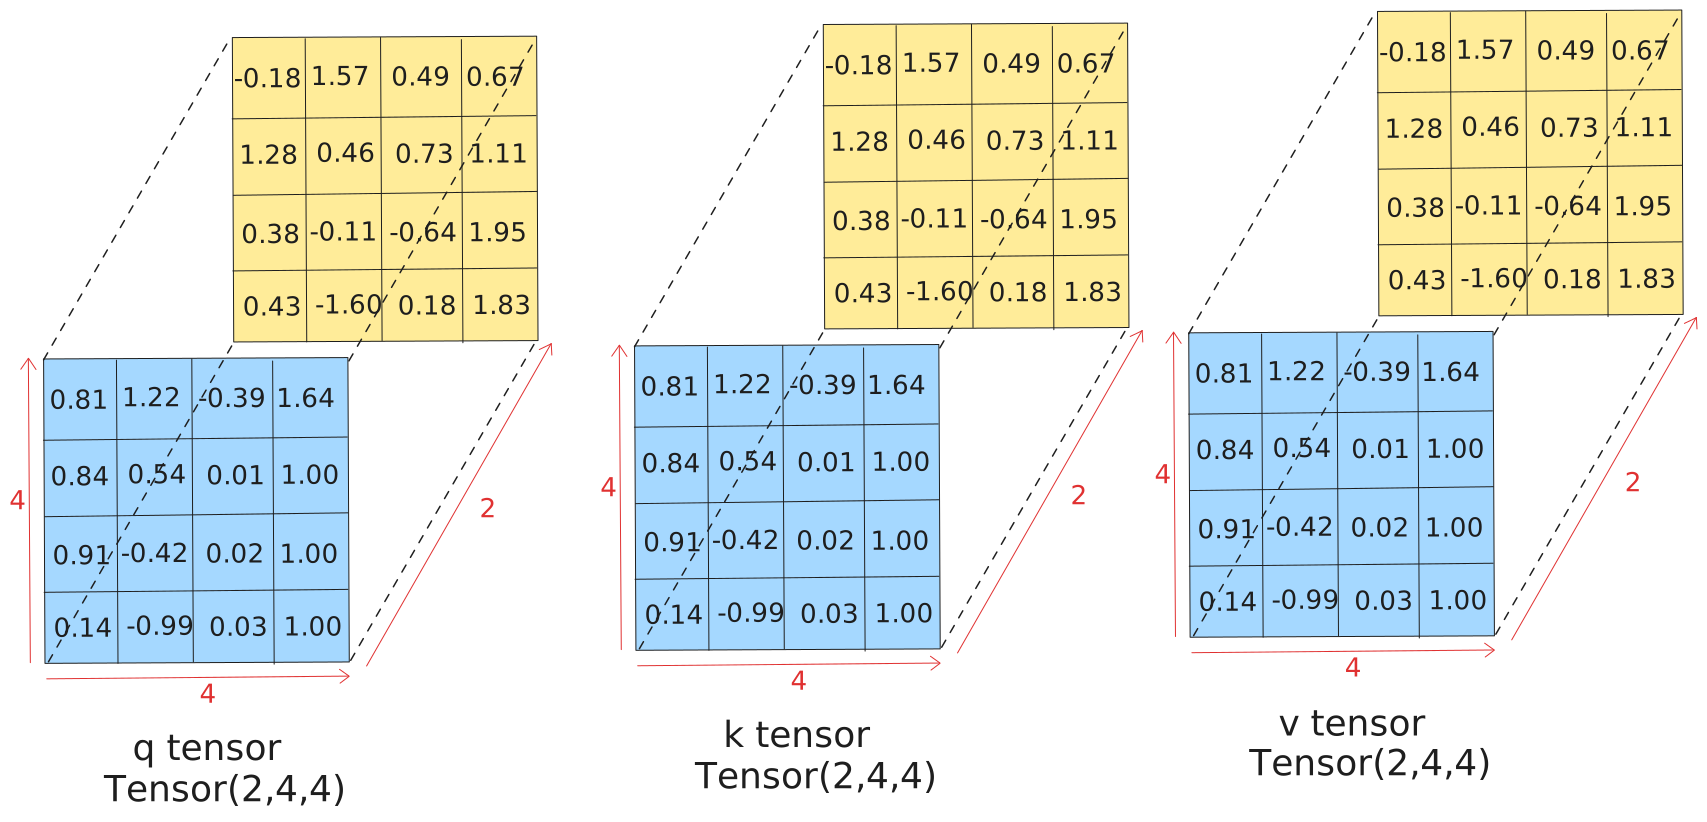
Q, K, V inputs — three identical copies of post-PE tensor · (2, 4, 4)
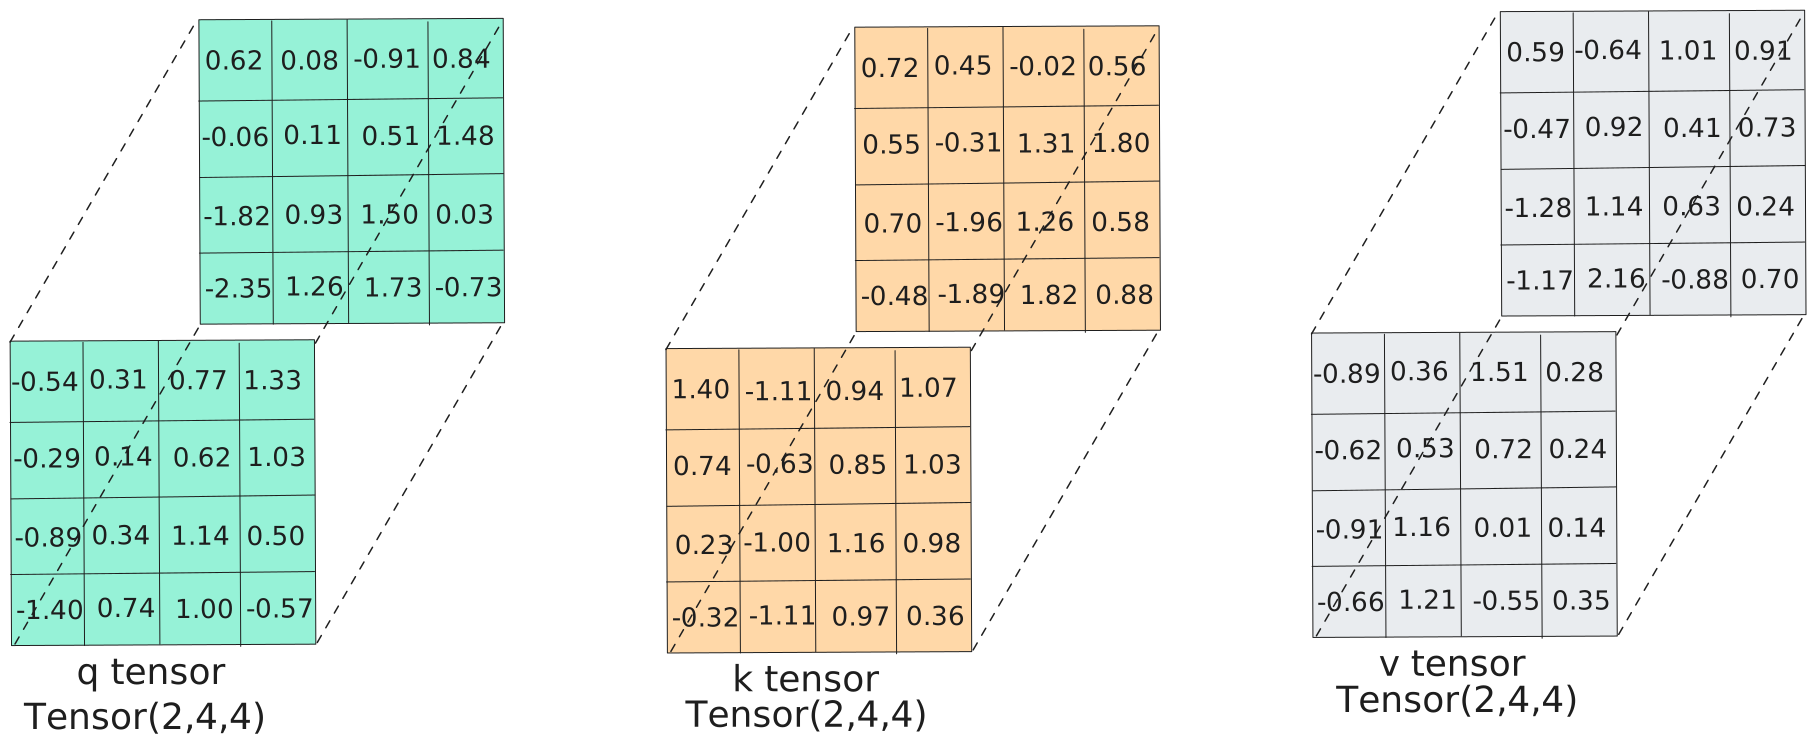
Q, K, V after projection — still (2, 4, 4) each
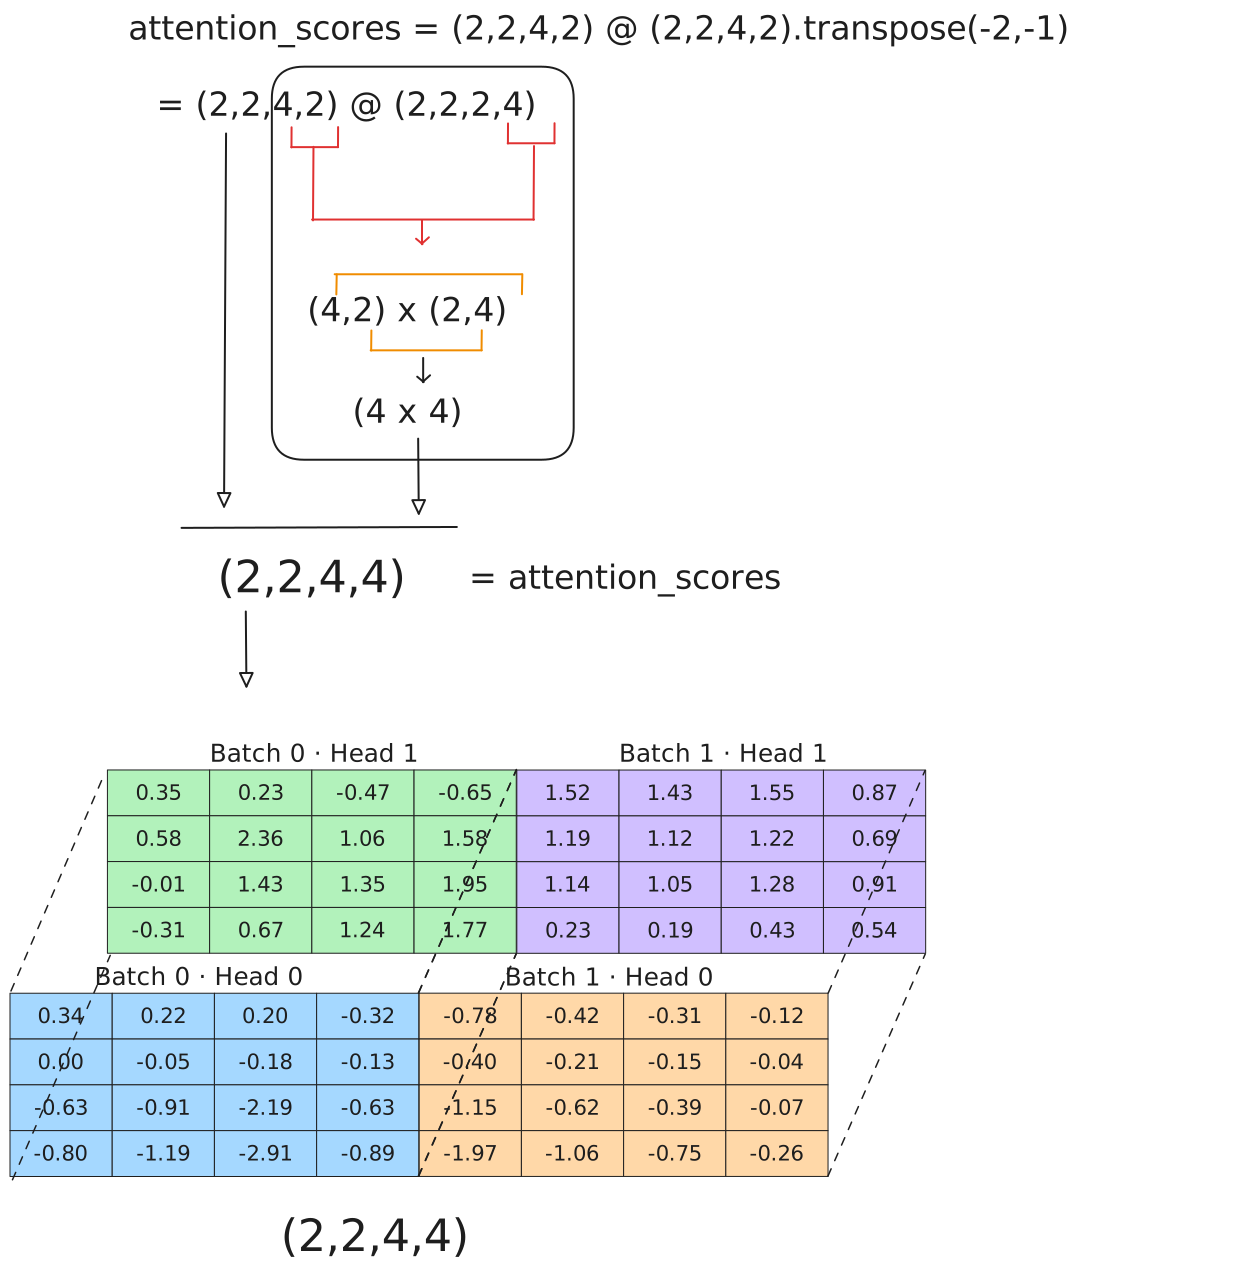
QK^T shape — (2,2,4,2) × (2,2,2,4) = (2,2,4,4) · heads split here
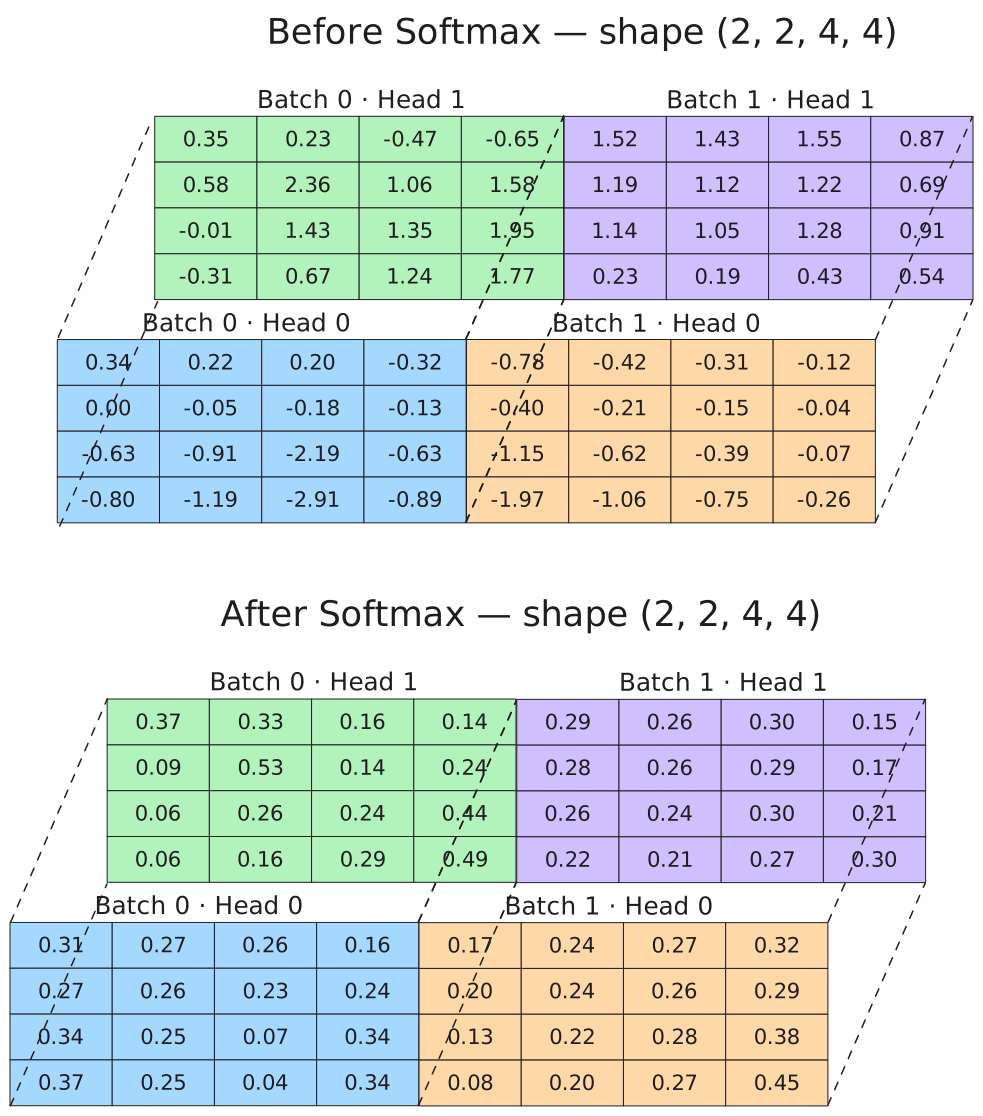
Attention scores before & after softmax · (2, 2, 4, 4)
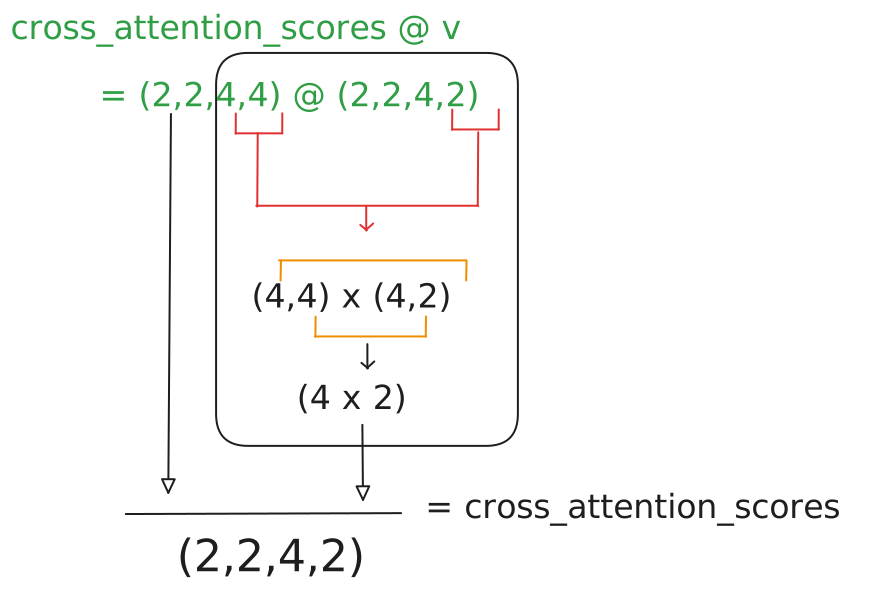
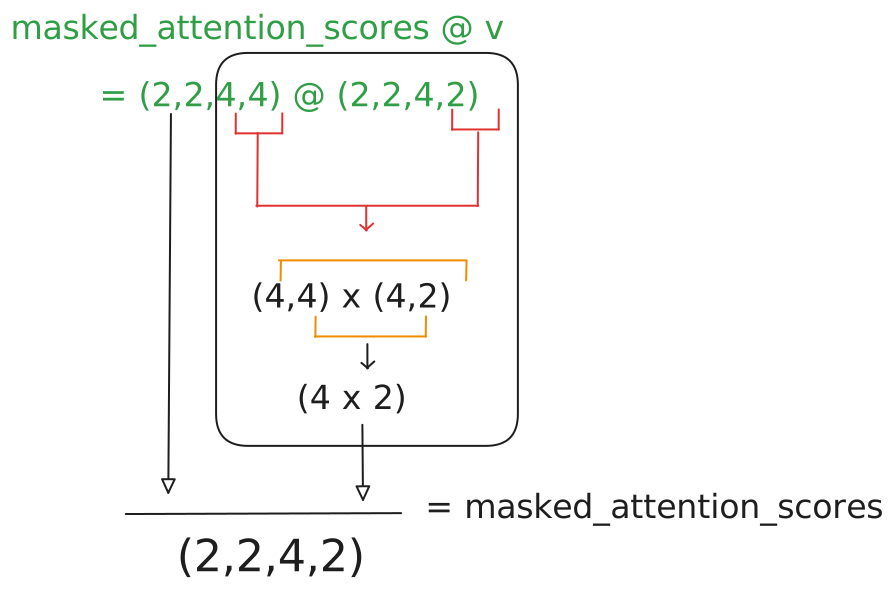
Scores × V — (2,2,4,4) × (2,2,4,2) = (2,2,4,2)
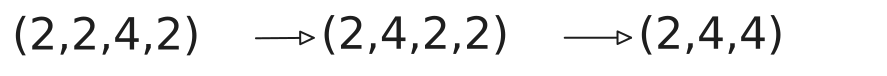
Concat heads + W_O — (2,2,4,2) → (2,4,4)
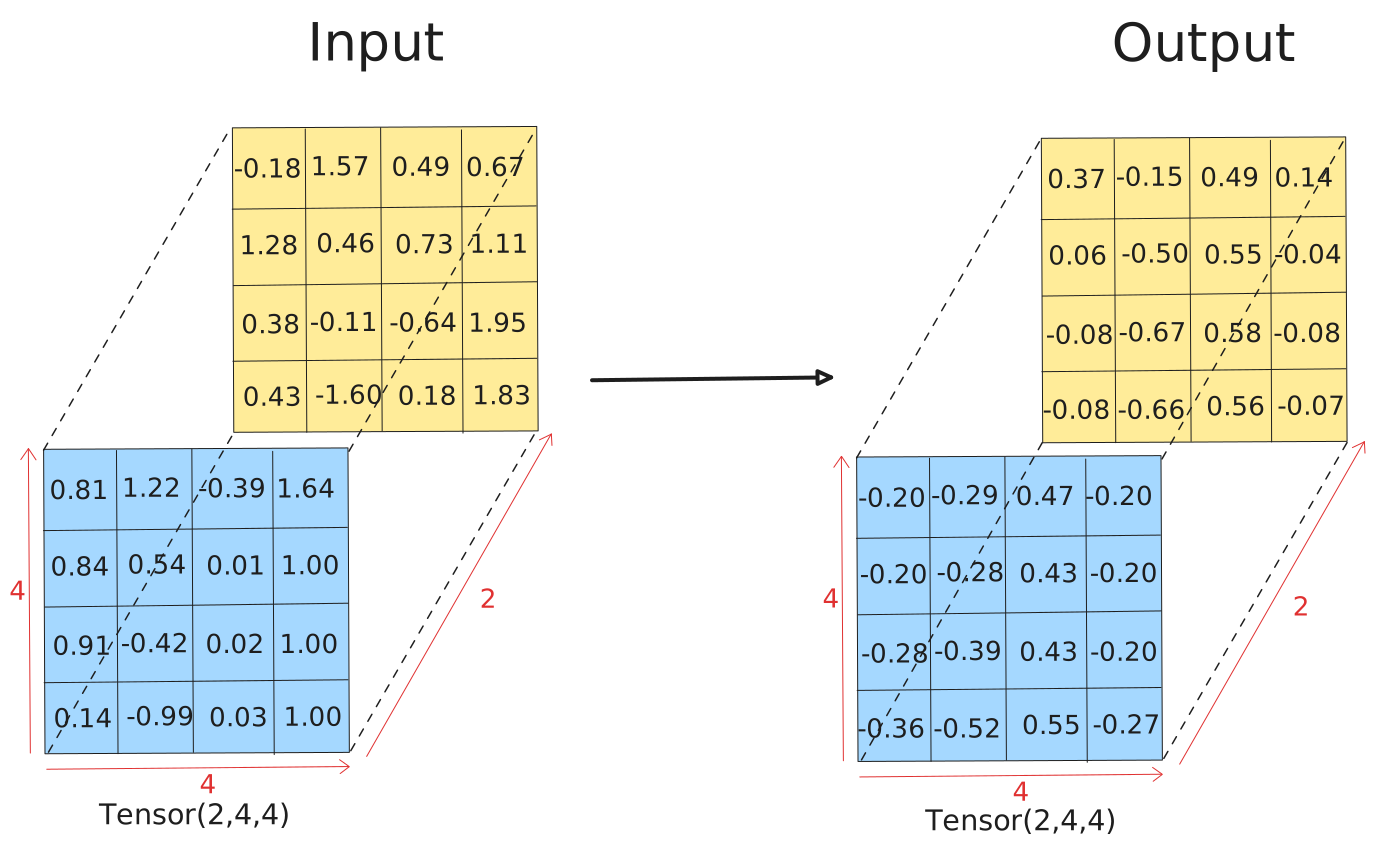
MHA summary — in (2,4,4) → out (2,4,4)
residual + LayerNorm (2, 4, 4) → (2, 4, 4)
04
Encoder: Add & Norm
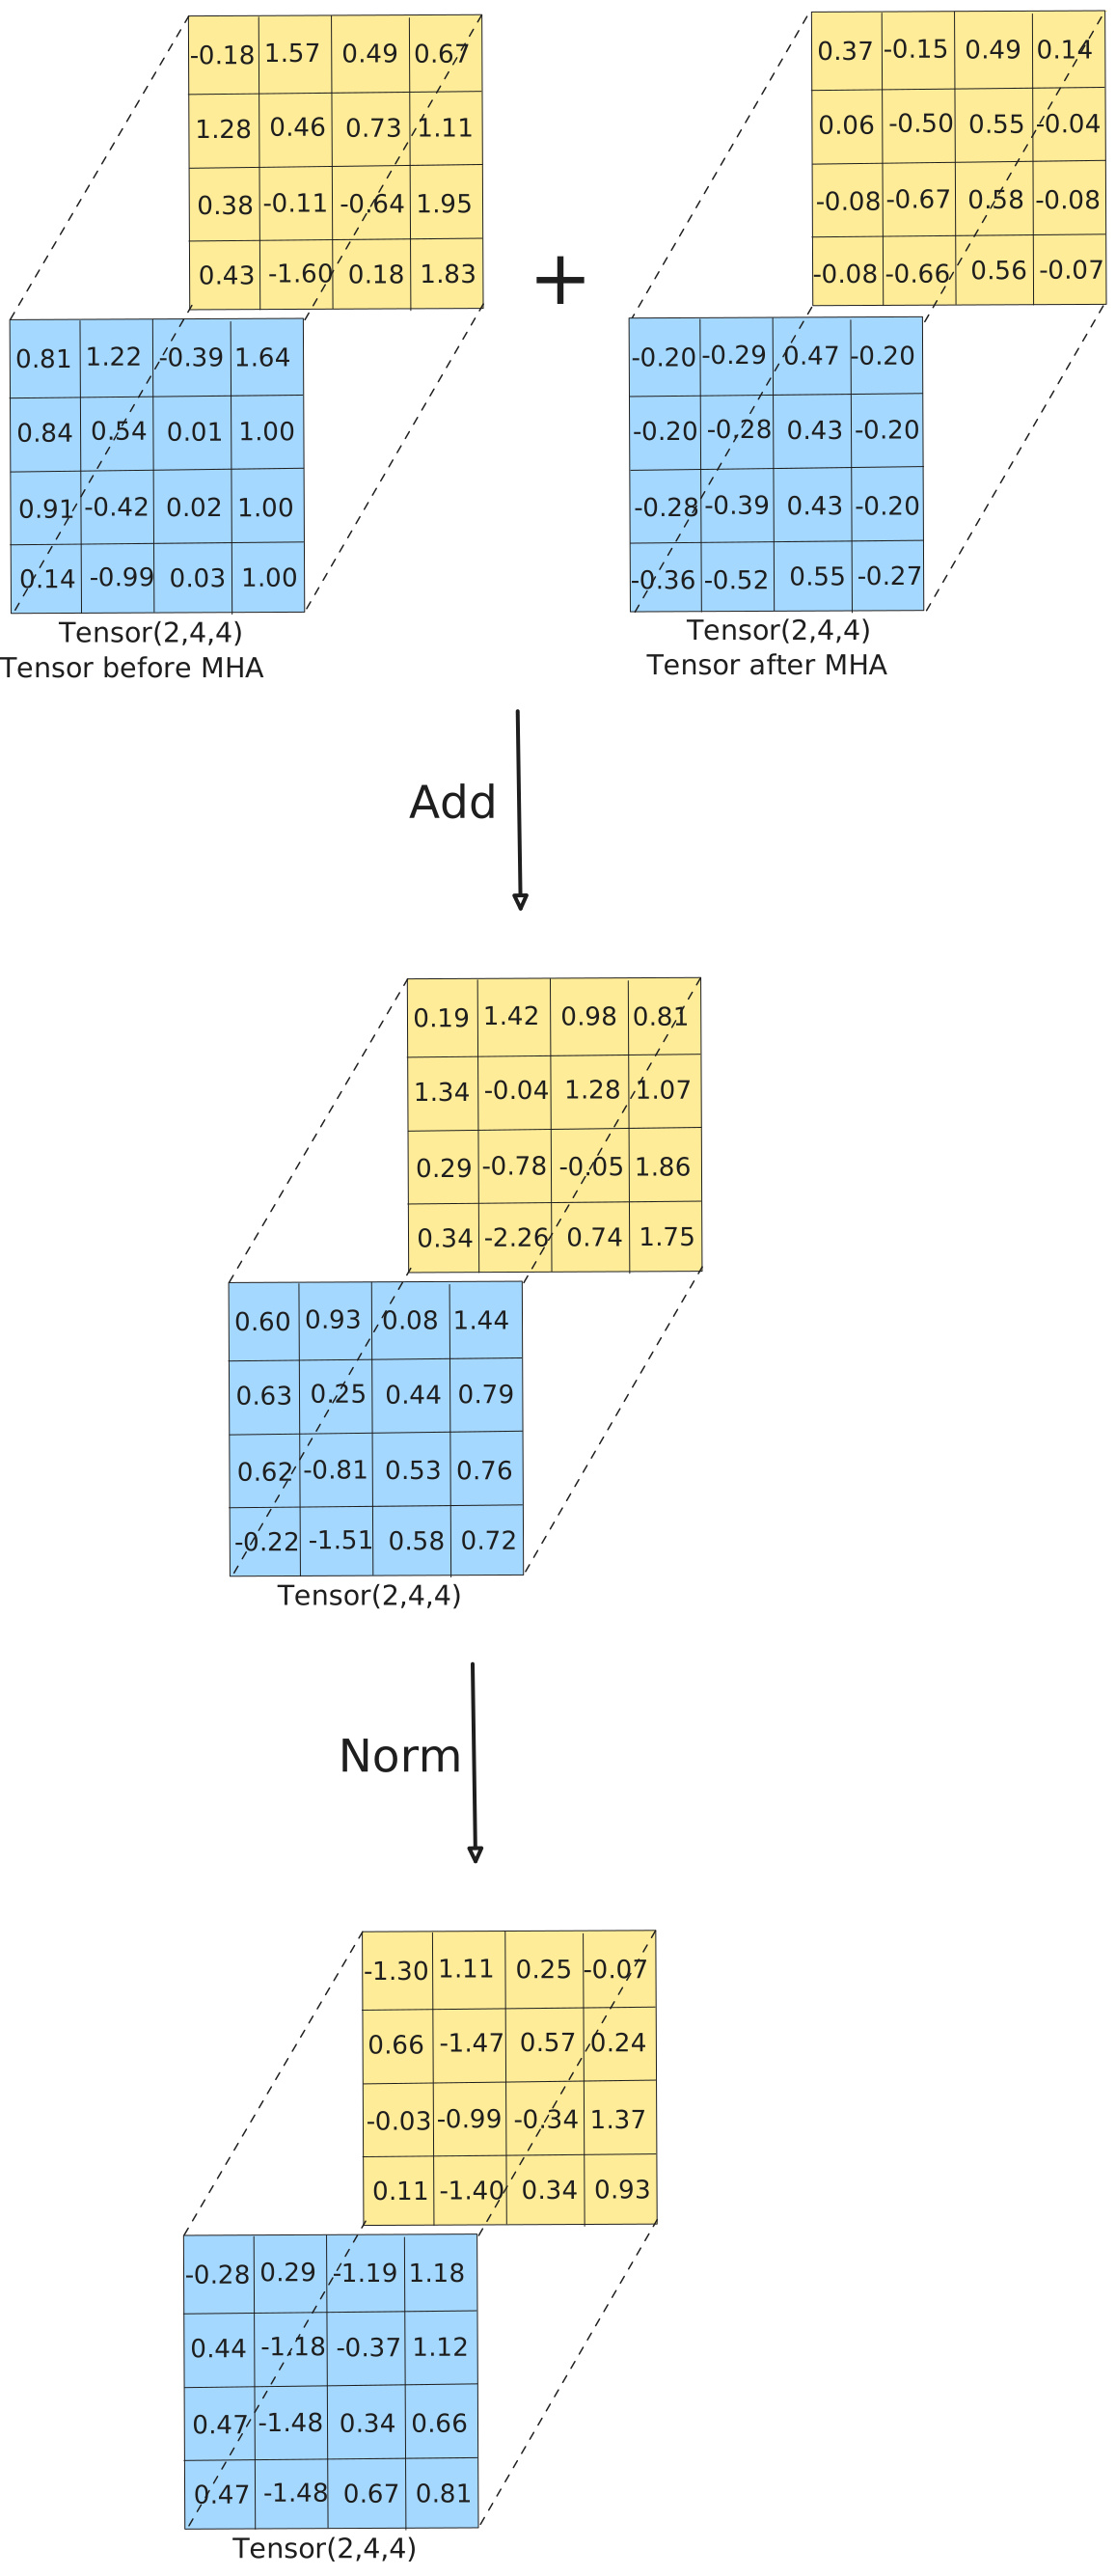
Add & Norm — in (2,4,4) → out (2,4,4)
Linear(4→16) → ReLU → Linear(16→4) expands then compresses
05
Encoder: Feed-Forward Network
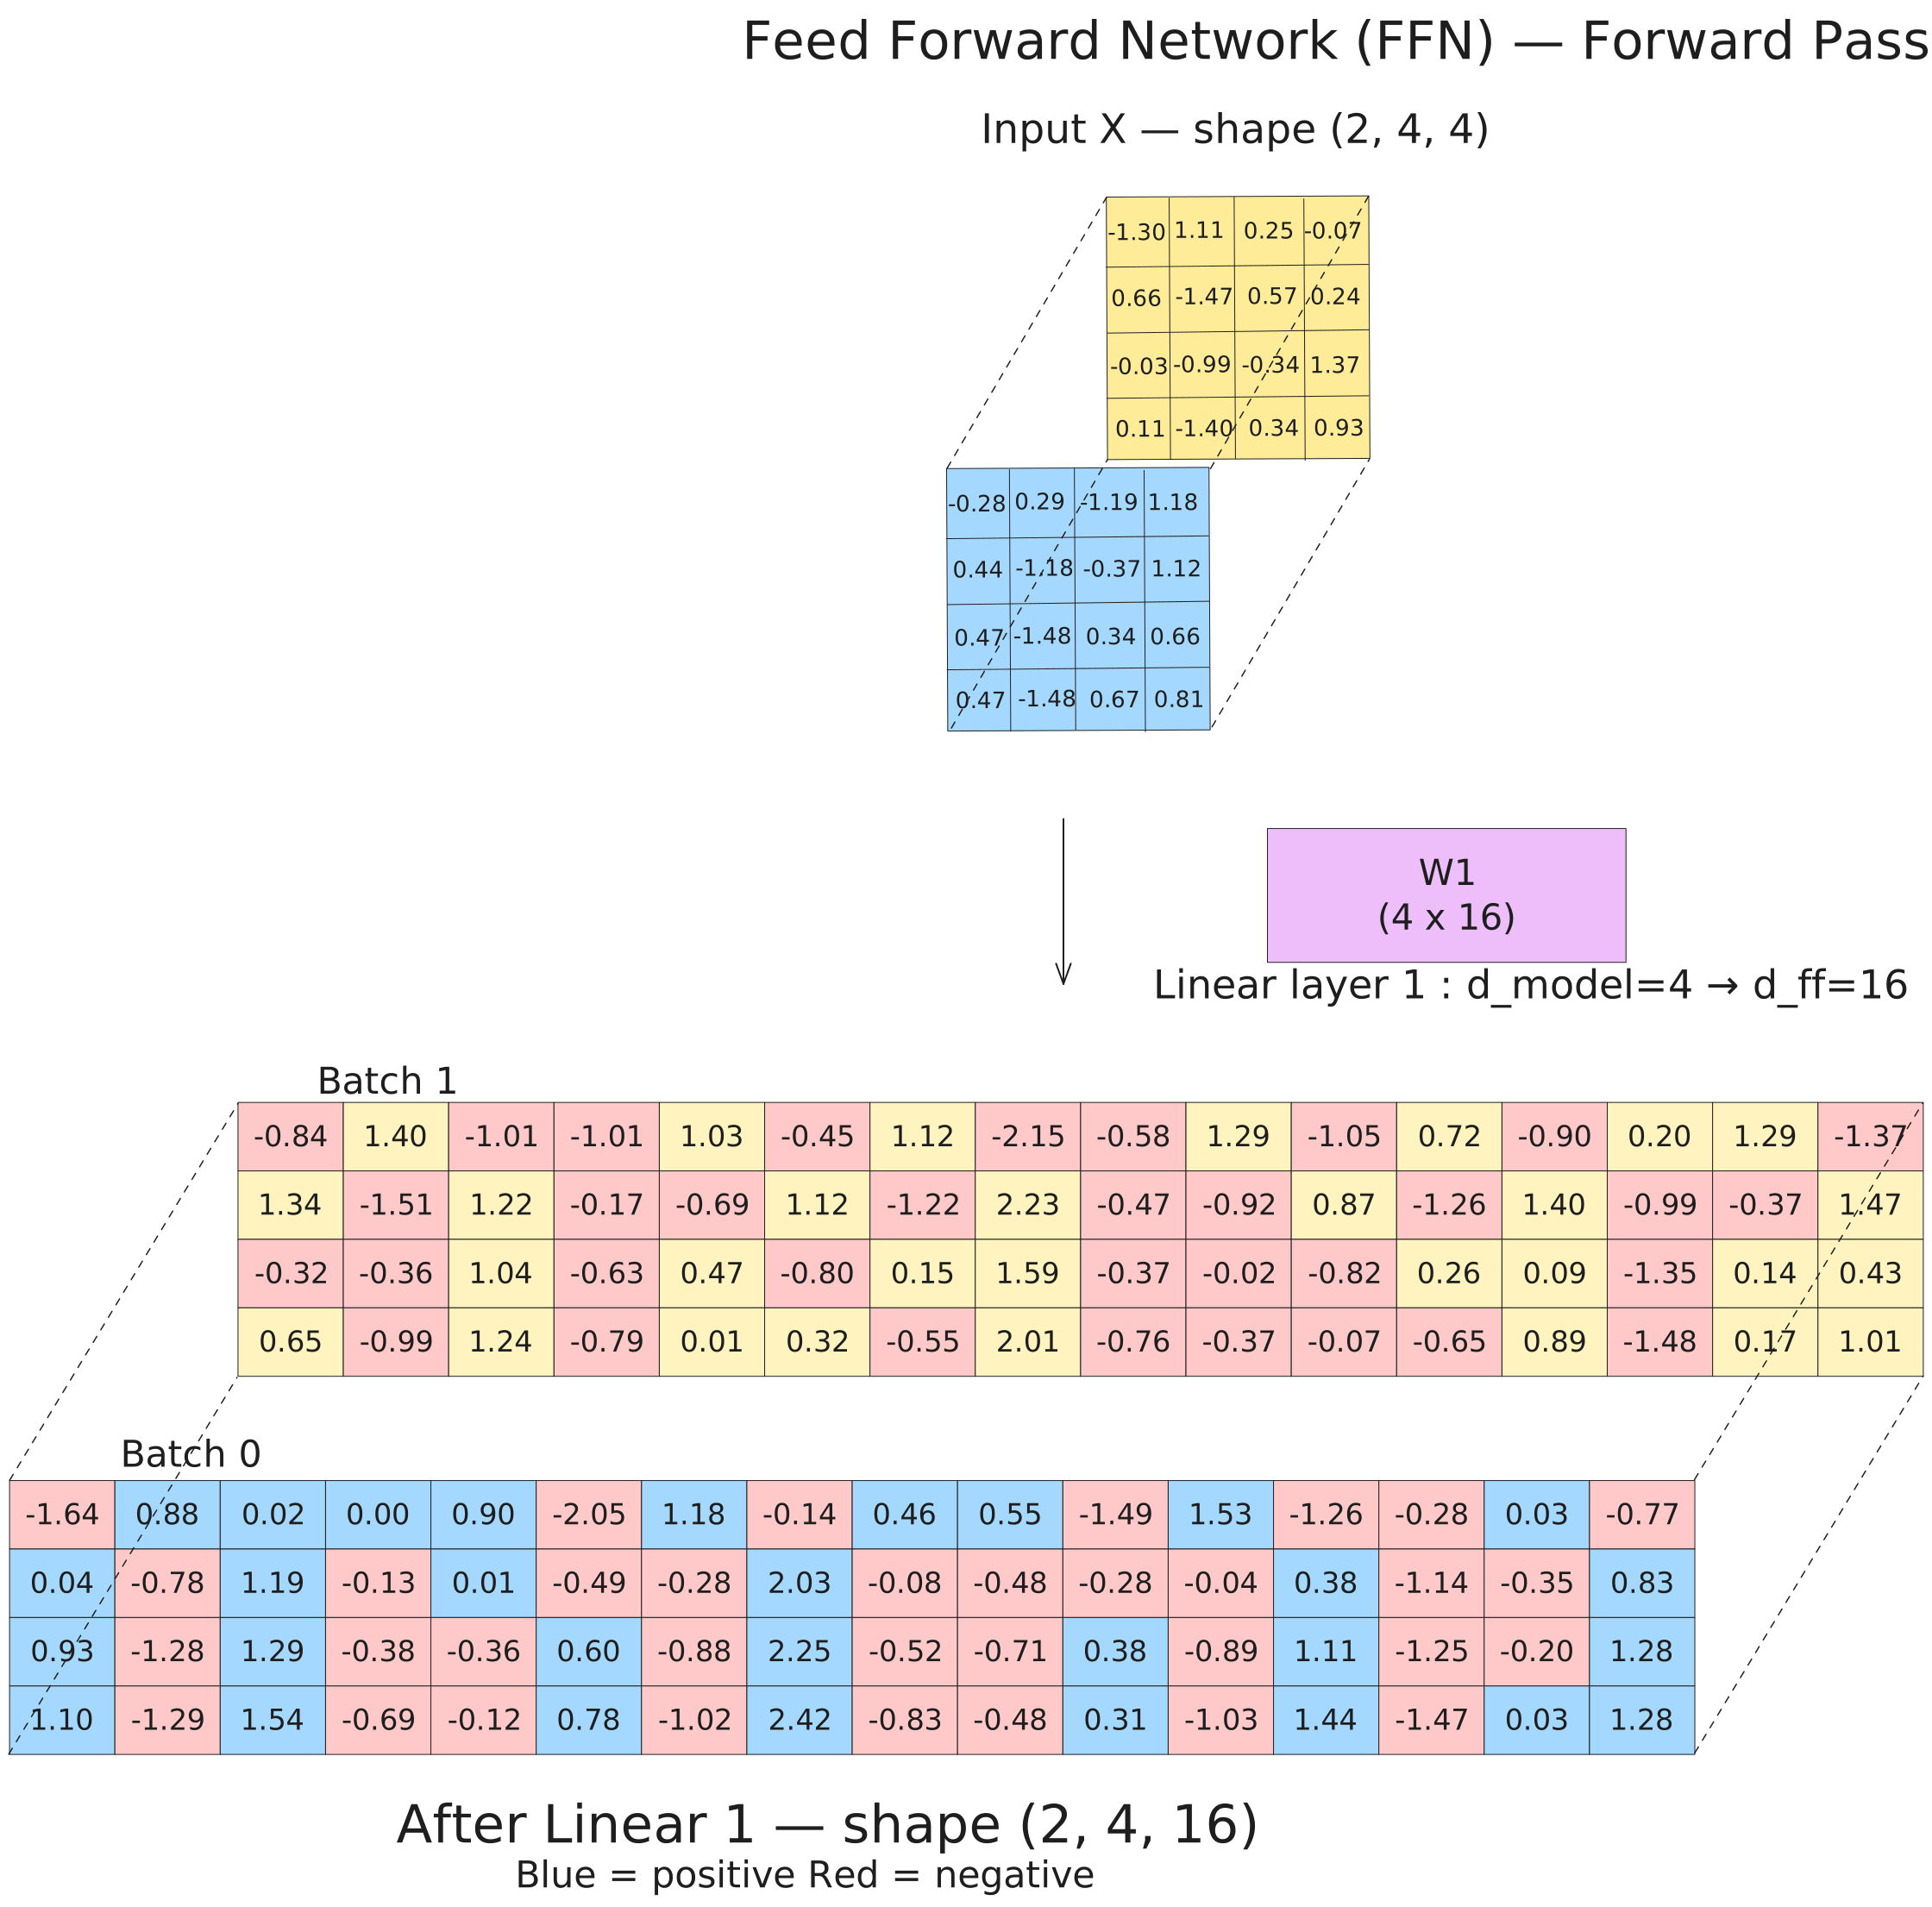
FFN — Linear(4→16), ReLU, Linear(16→4)
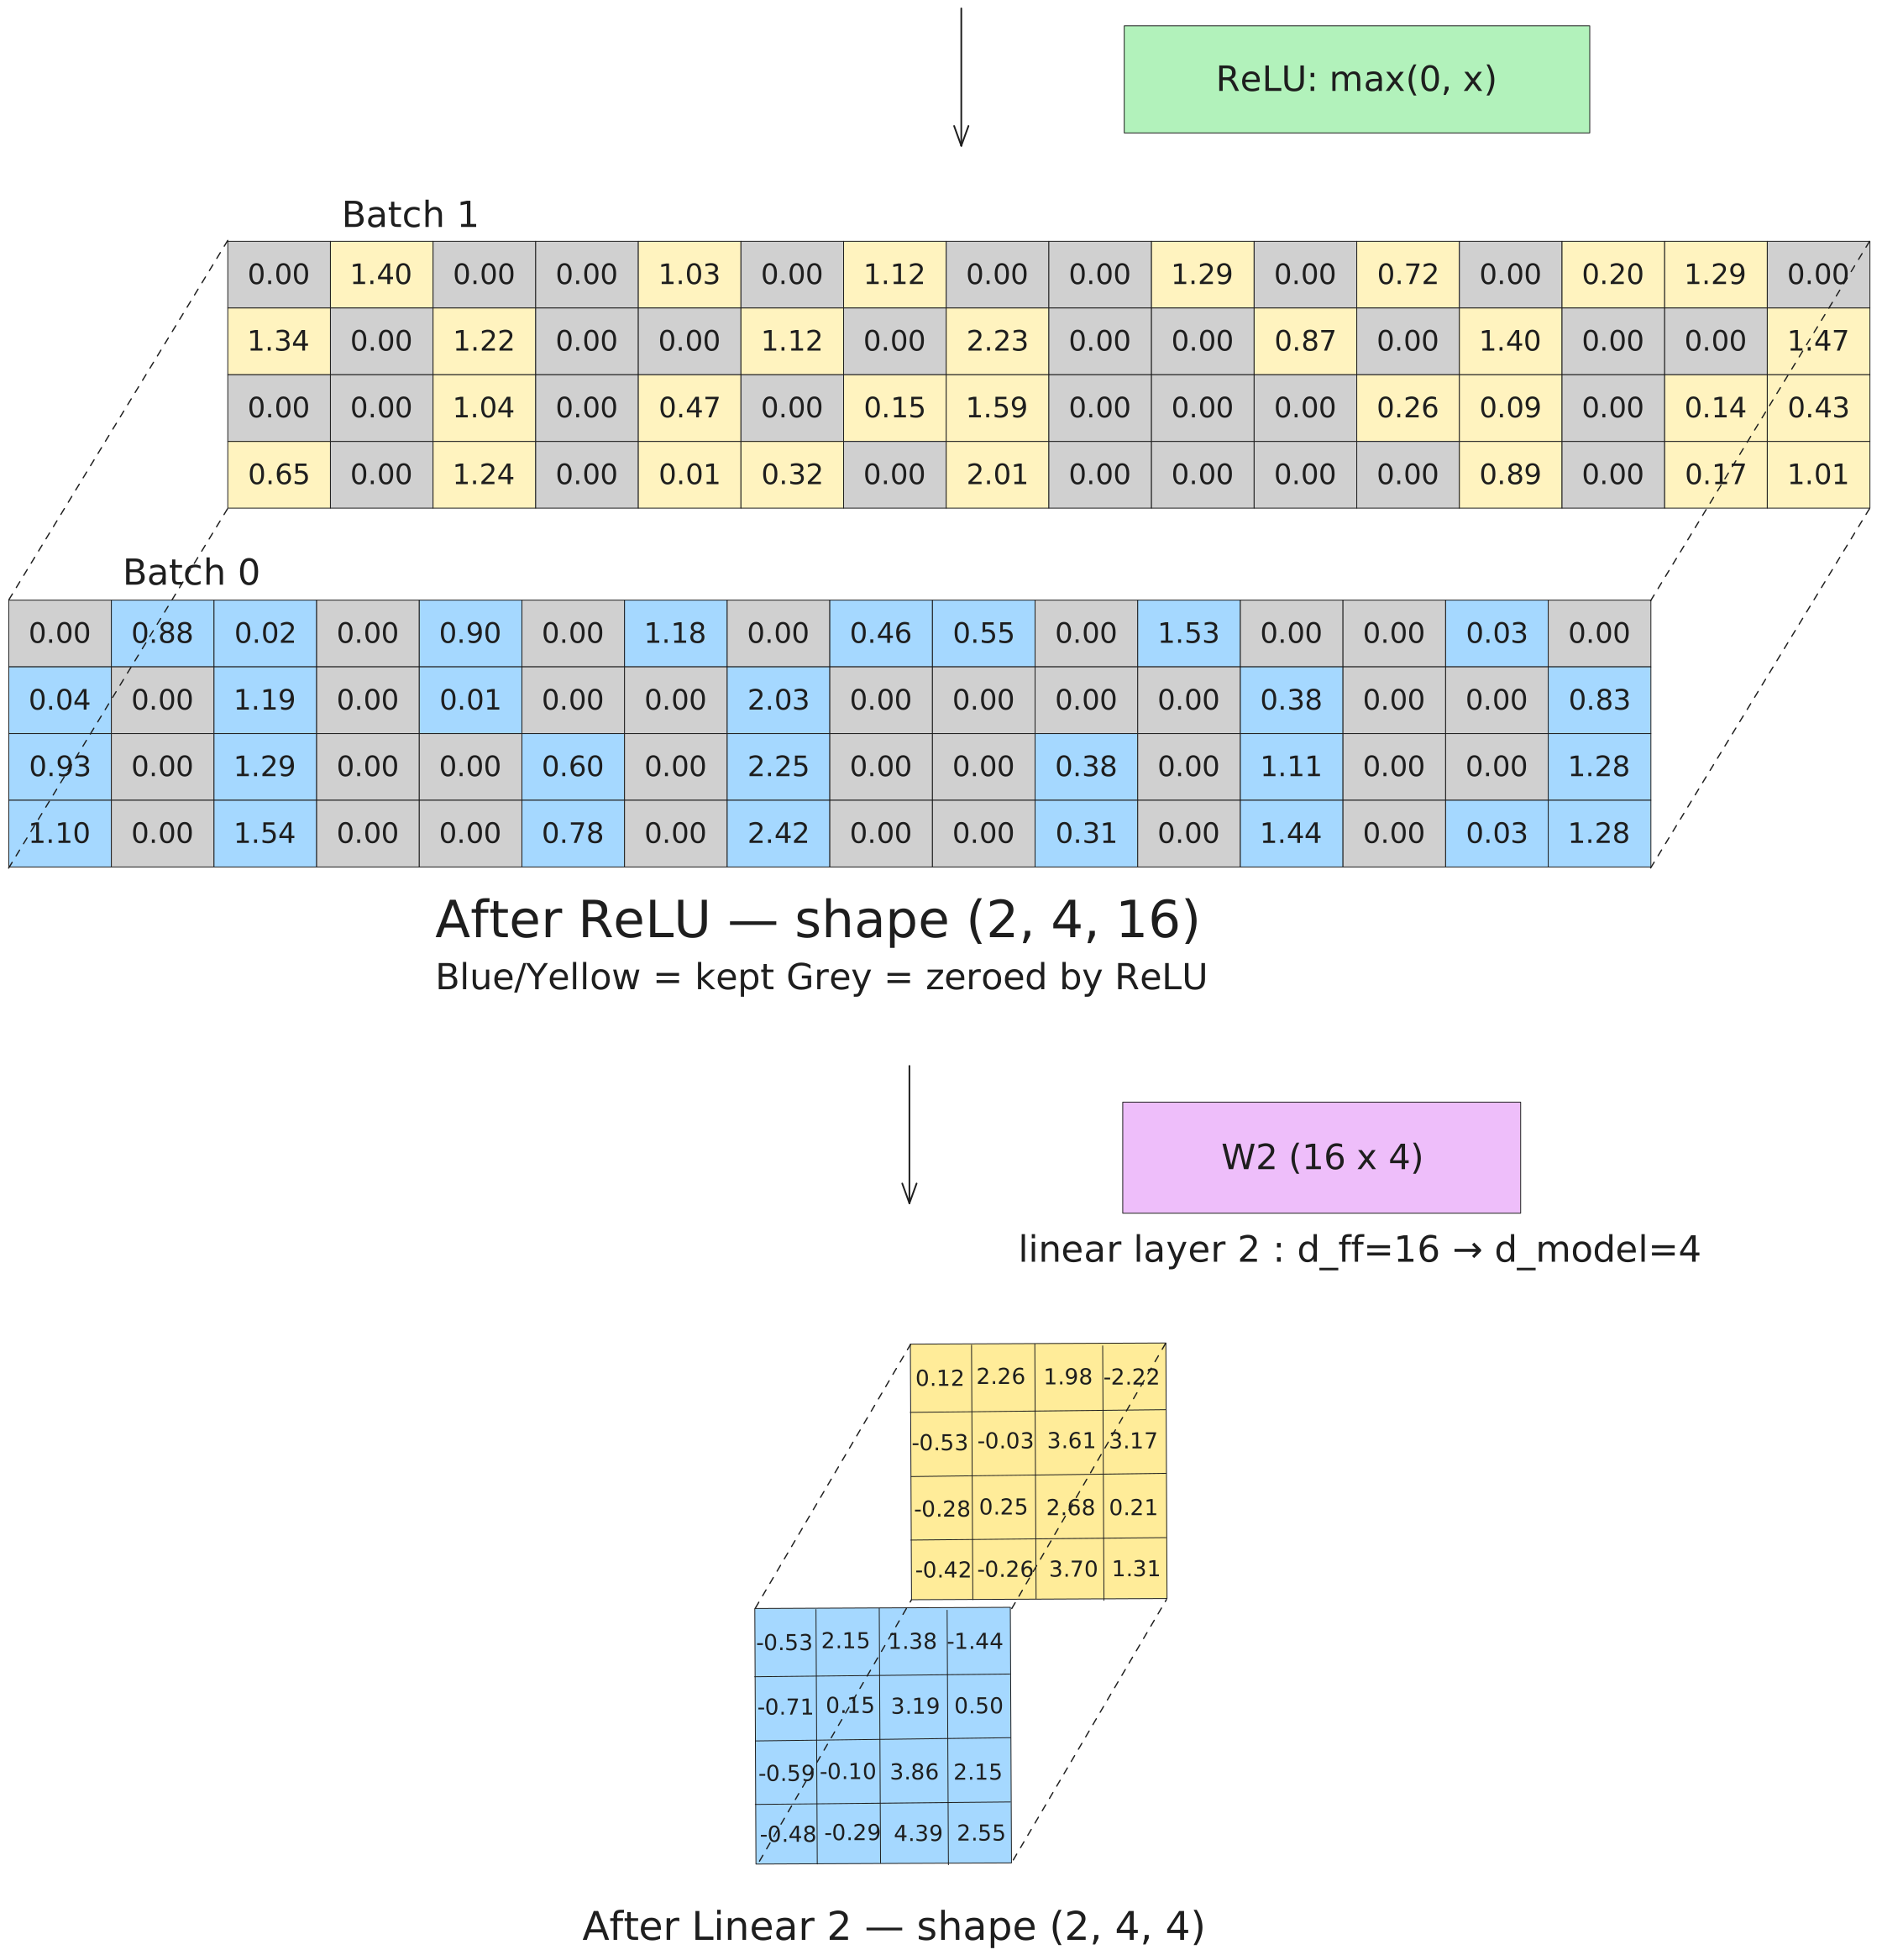
After ReLU — negatives zeroed · (2, 4, 16)
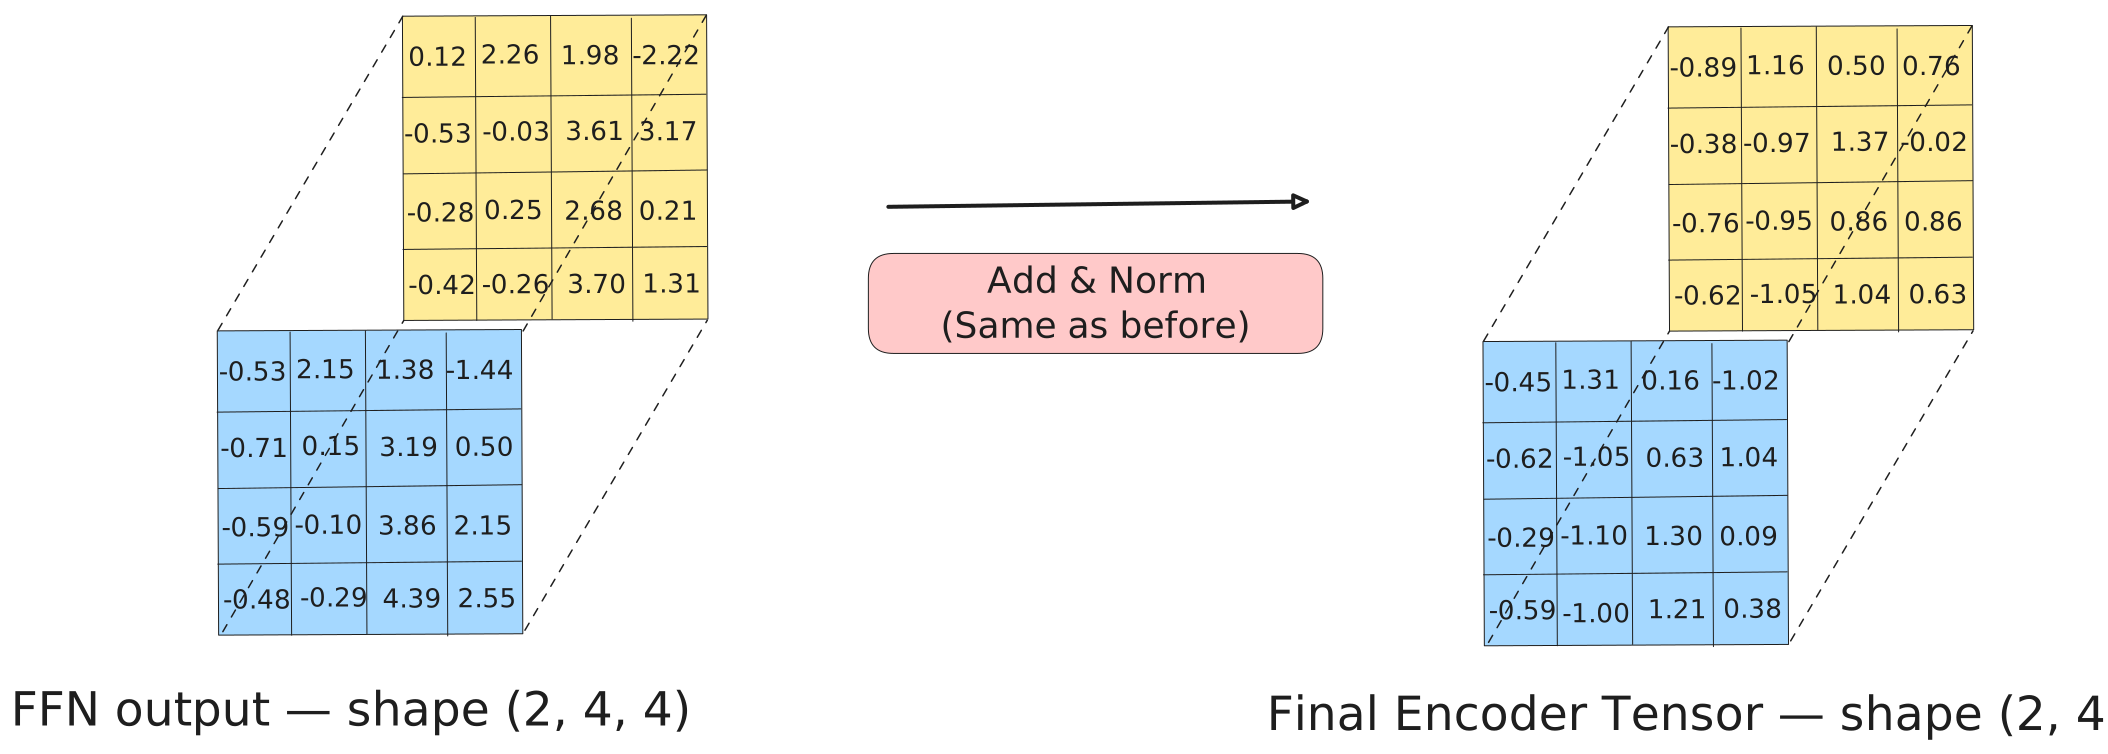
After Linear2 + Add & Norm — back to (2, 4, 4)
encoder complete output (2, 4, 4) → decoder cross-attention
06
Encoder Output
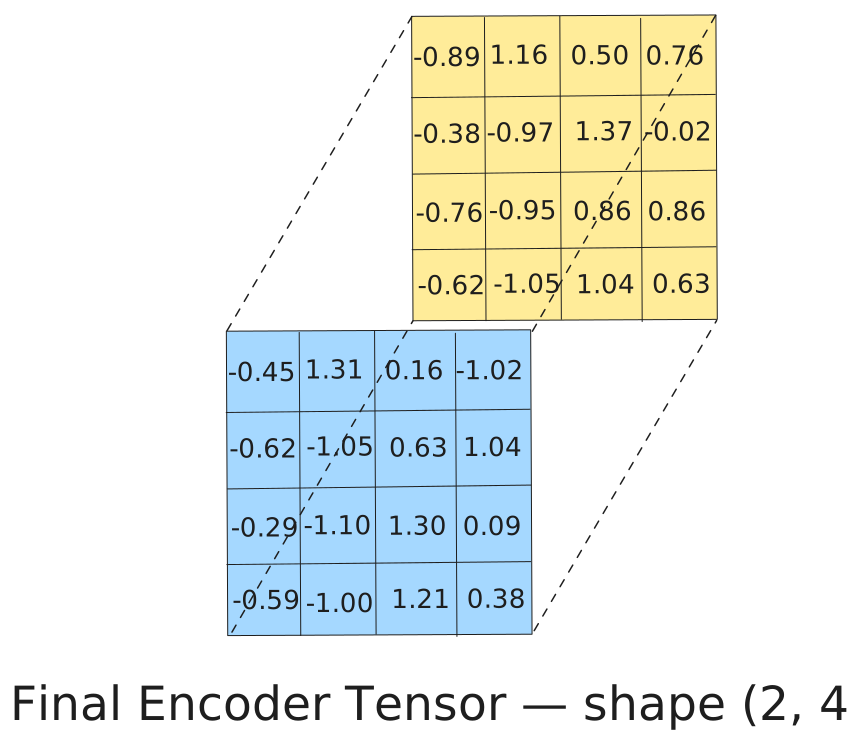
Final encoder output · (2, 4, 4)
Encoder done · Decoder begins
Decoder block — conceptual overview
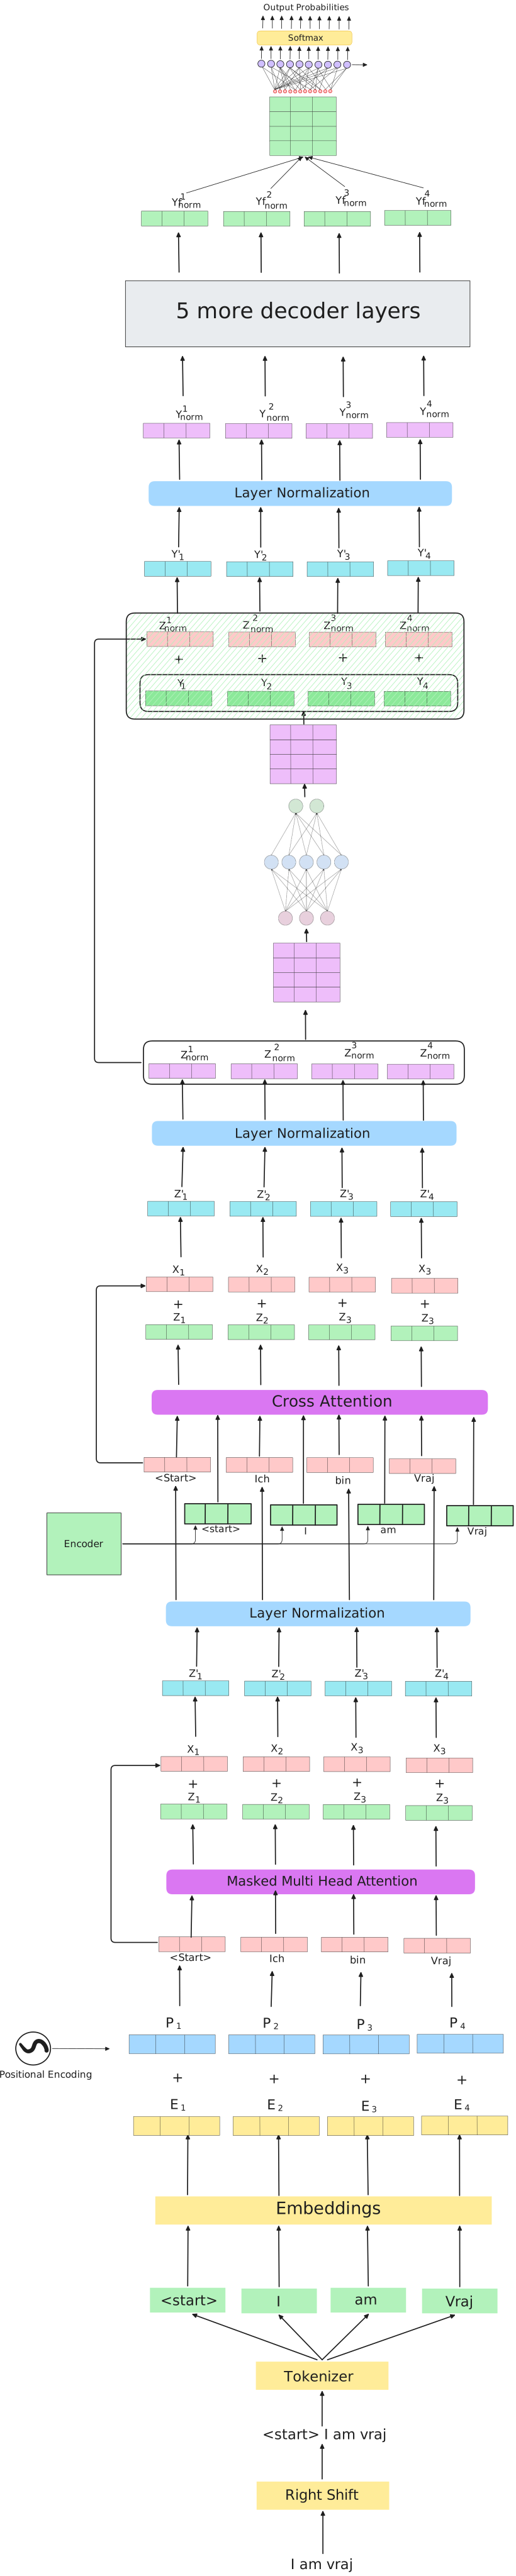
Full decoder: masked self-attention → cross-attention → FFN, each with Add & Norm
07
Decoder: Setup & Embeddings
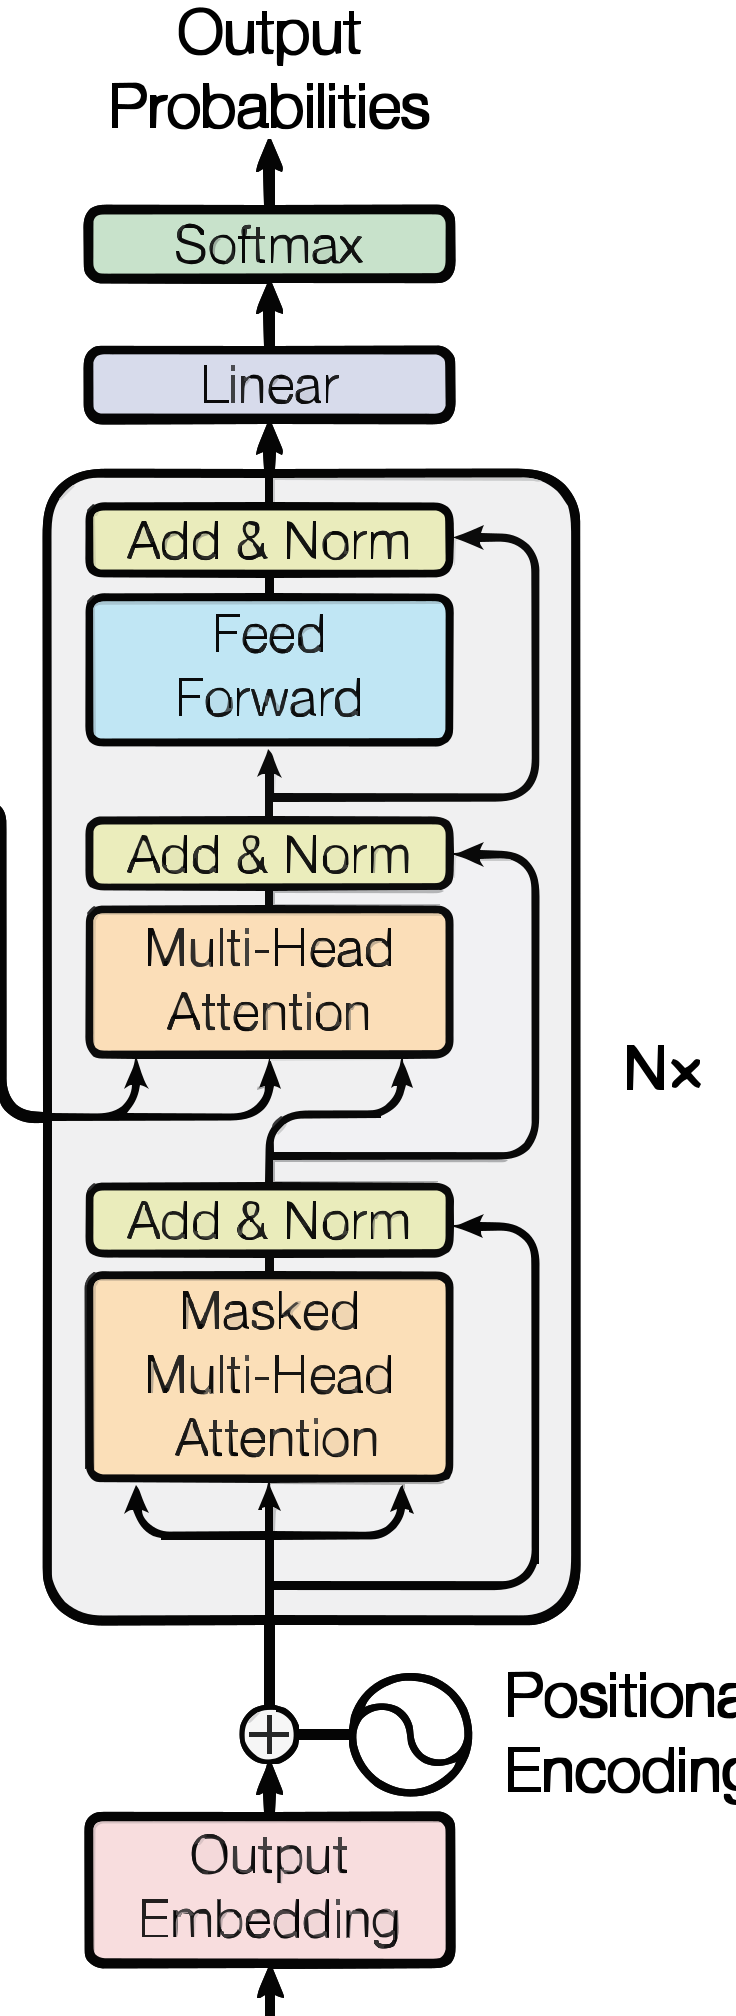
Decoder block — masked MHA · cross-attn · FFN
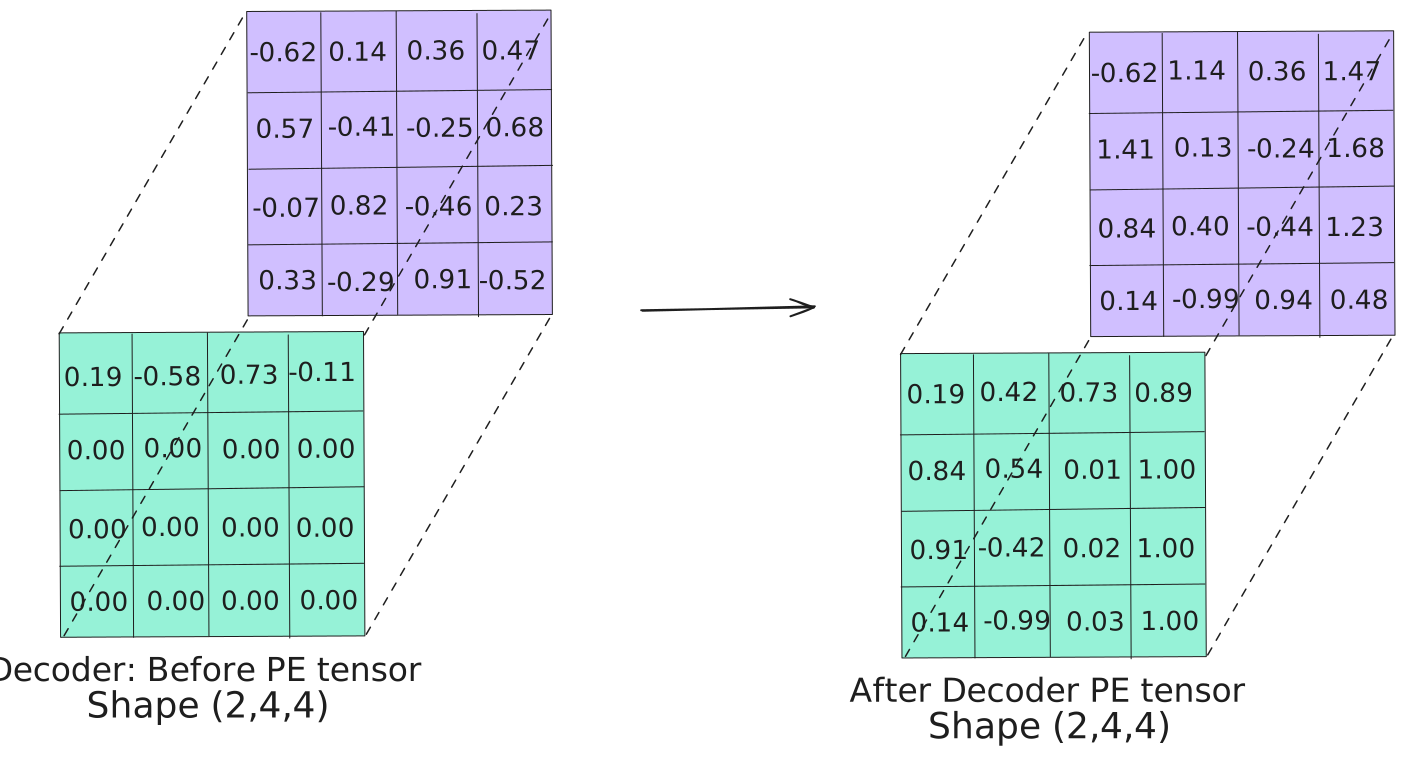
German tokens — before & after positional encoding · (2, 4, 4)
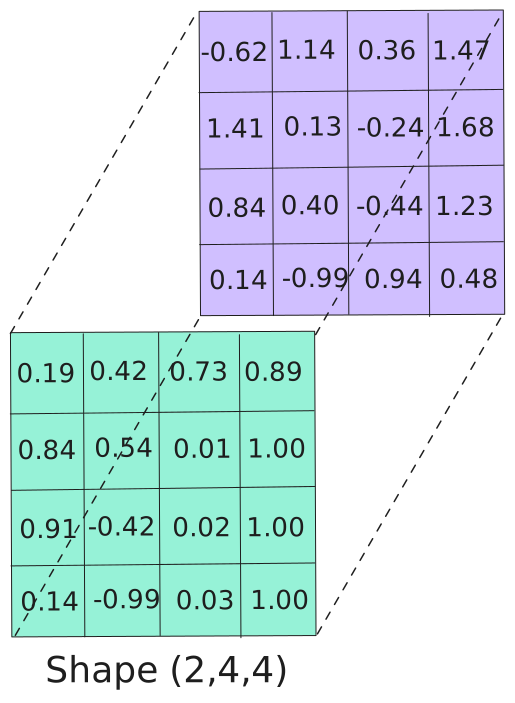
Decoder input after PE · (2, 4, 4)
self-attention with causal mask future positions → −1e9
08
Decoder: Masked Multi-Head Attention
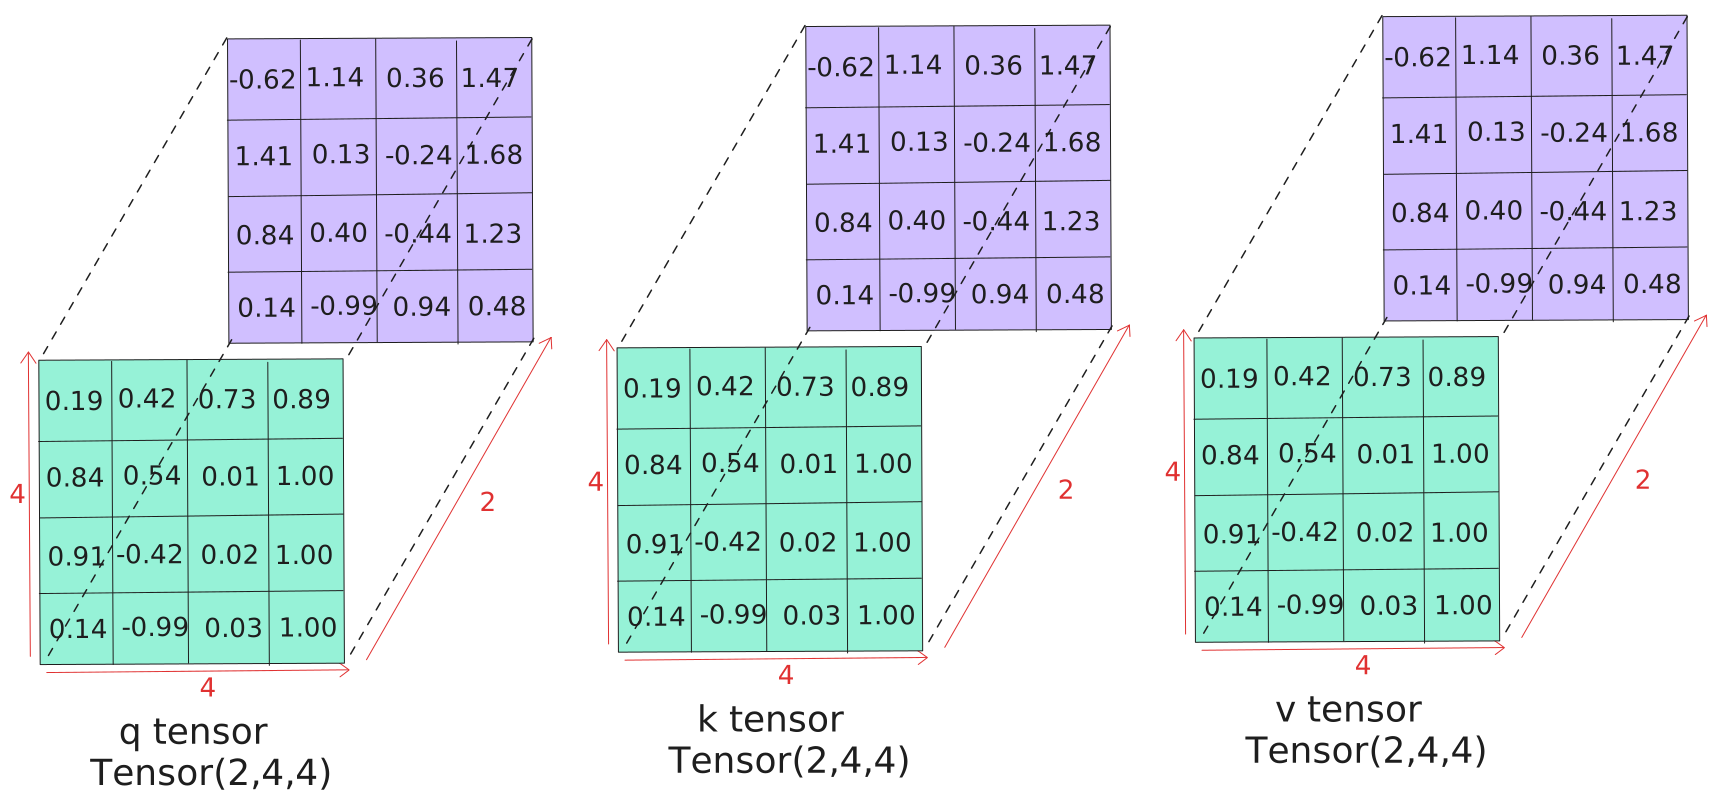
Q, K, V inputs — post-PE decoder tensor · (2, 4, 4)
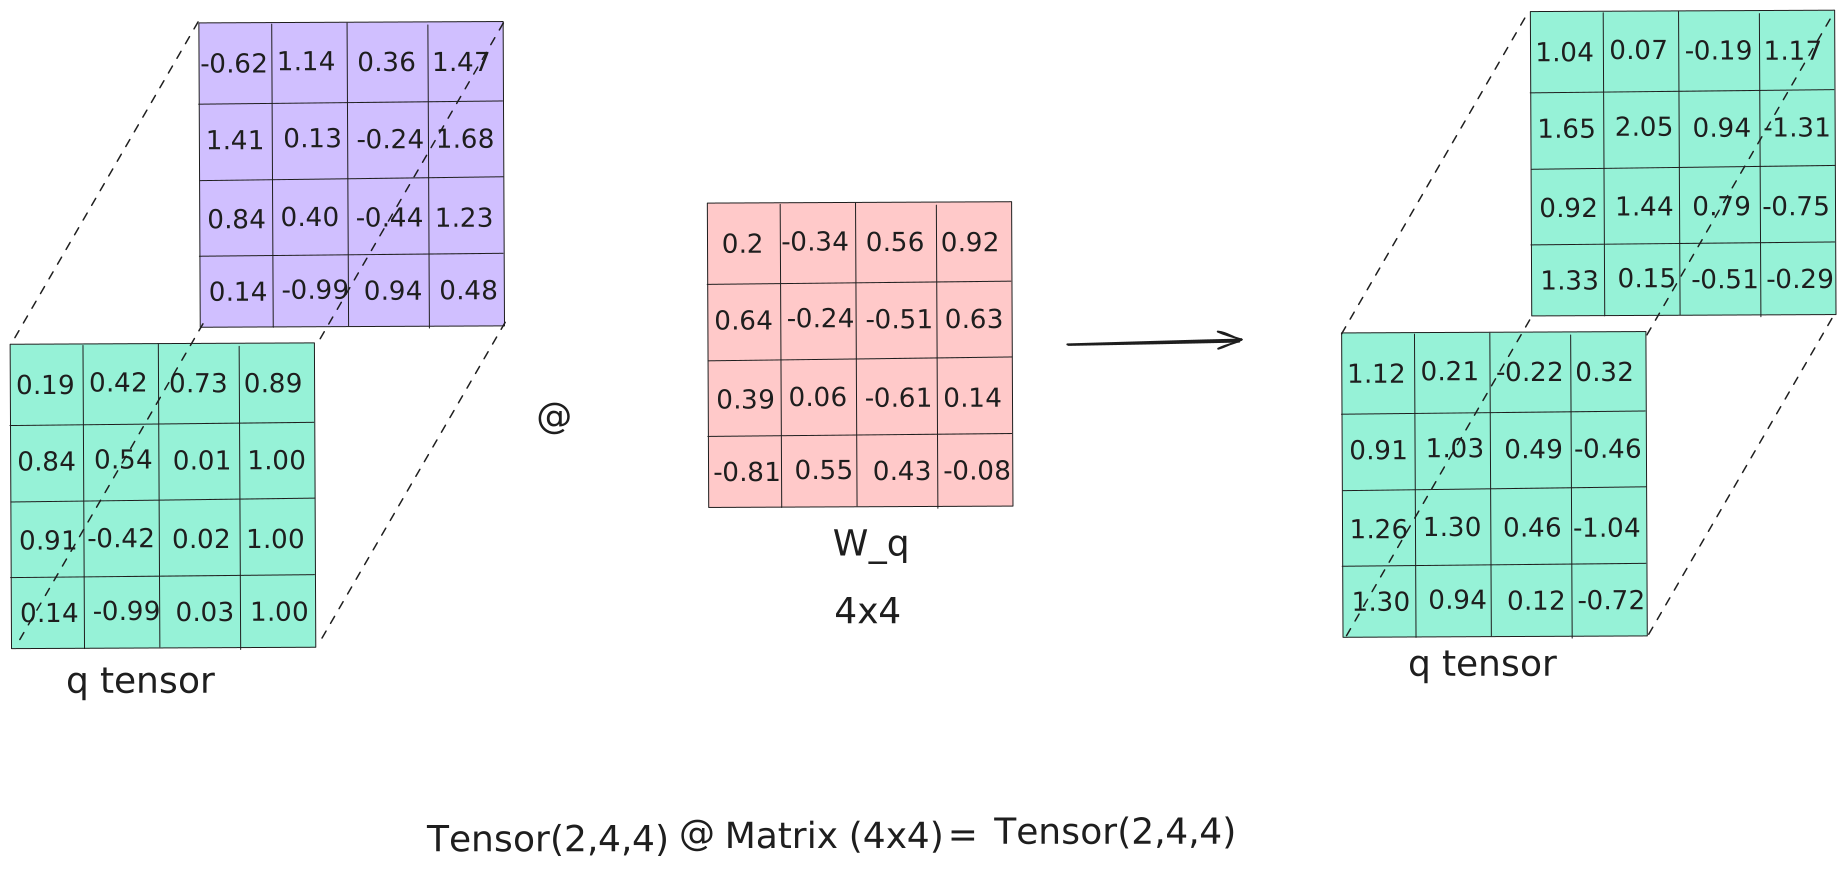
Q = x · W_Q.T
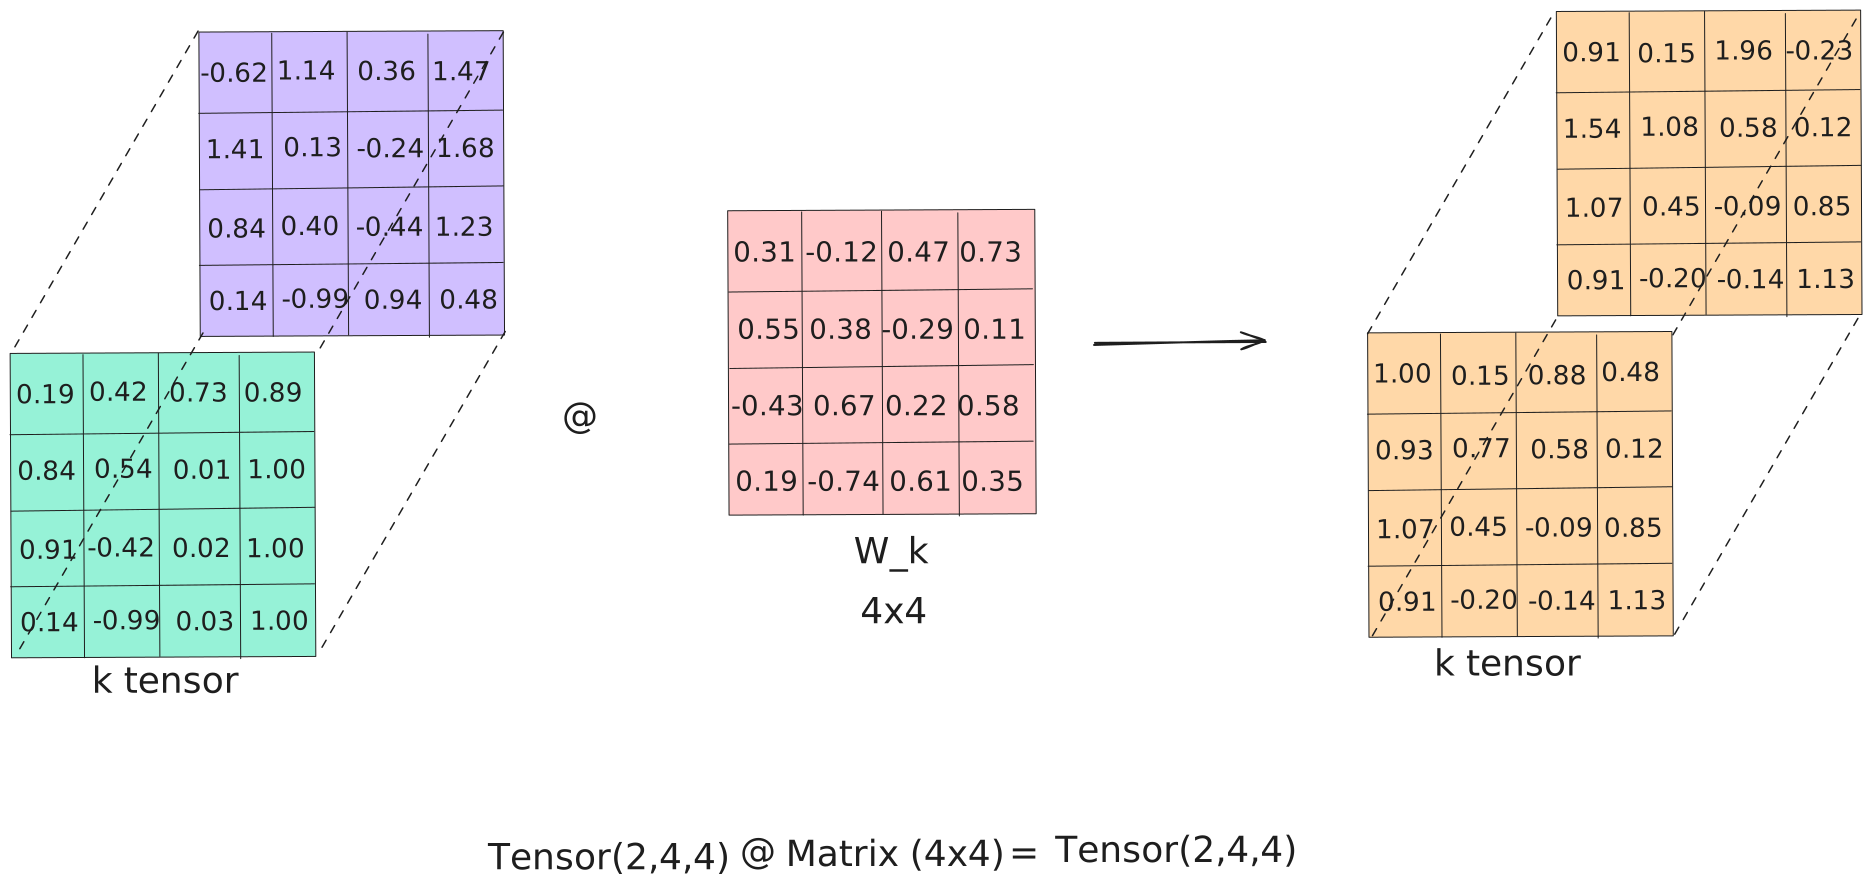
K = x · W_K.T
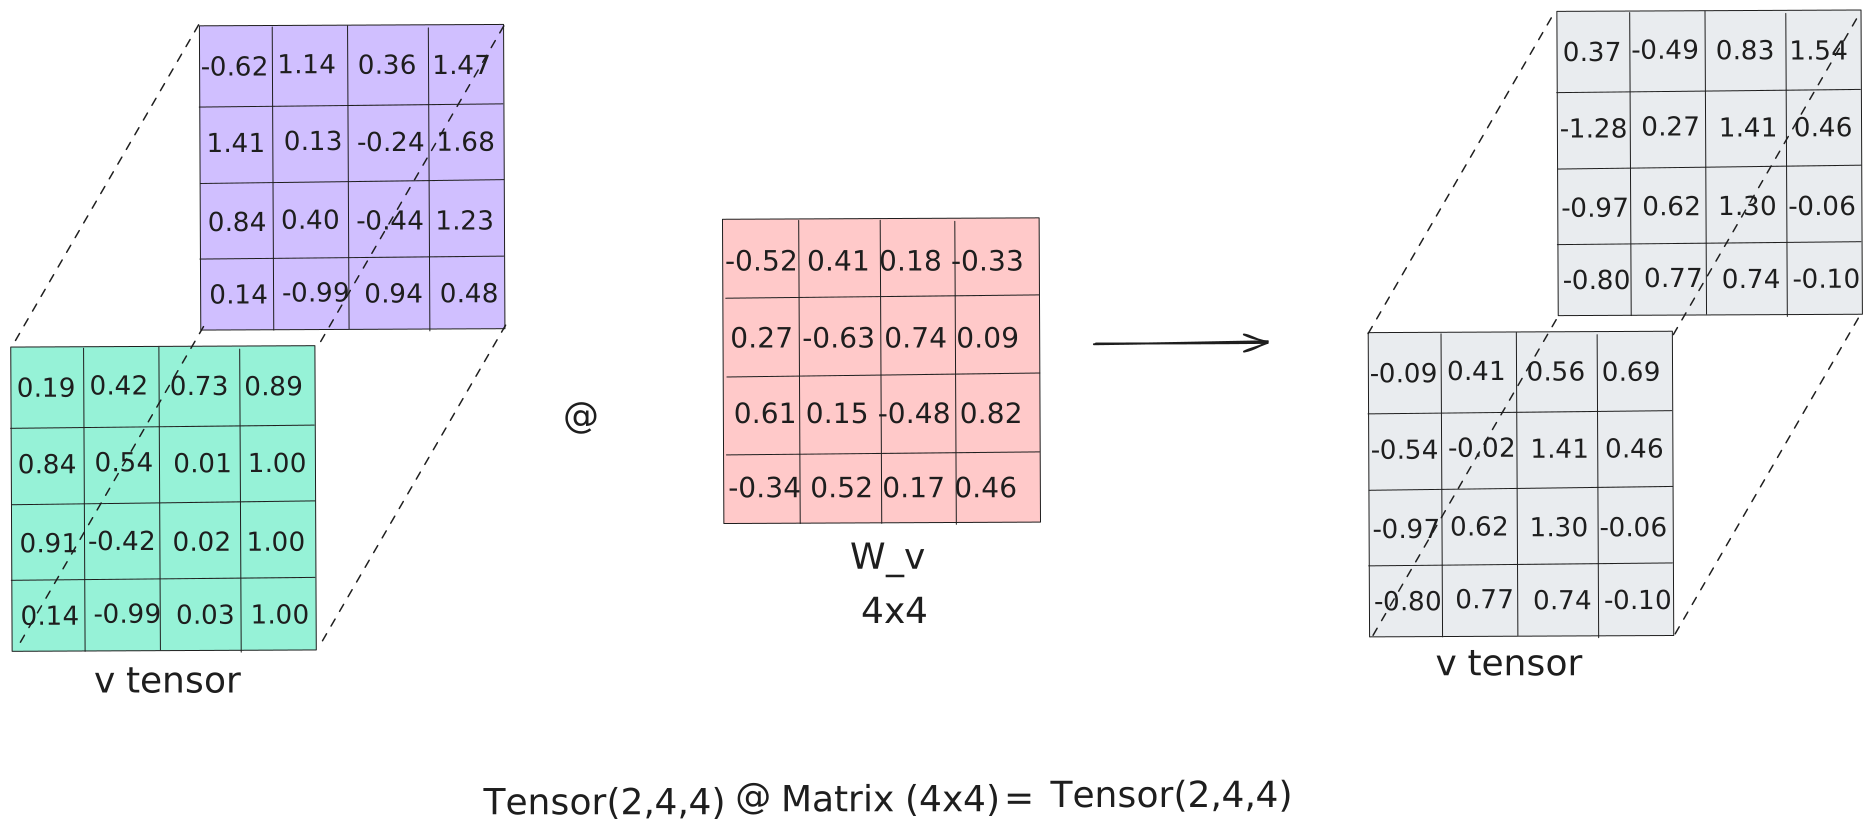
V = x · W_V.T
Masked fill — future & PAD positions set to −1e9 · (2, 2, 4, 4)
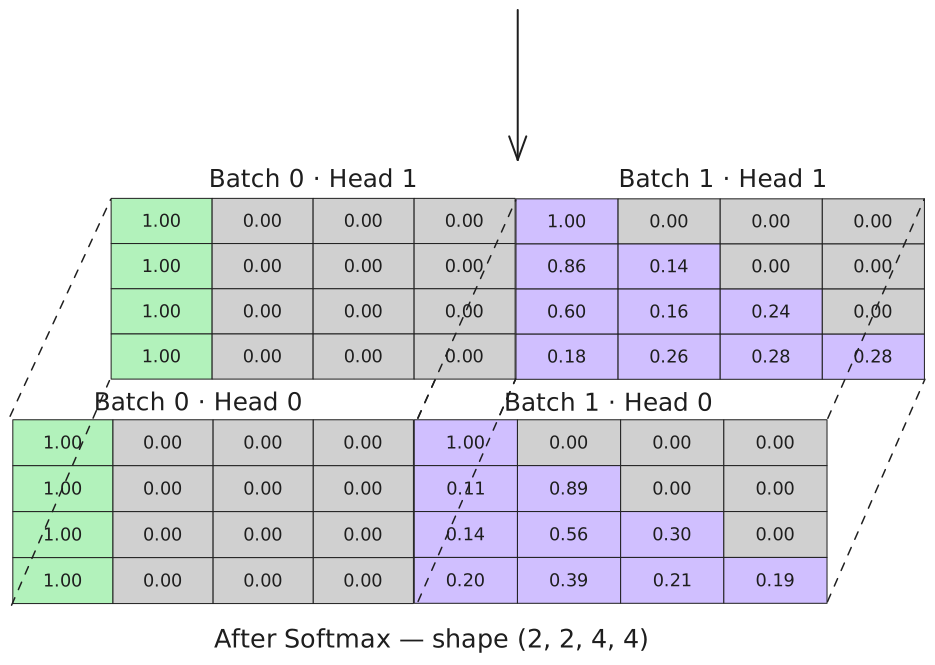
After softmax — causal staircase in Batch 1 · (2, 2, 4, 4)
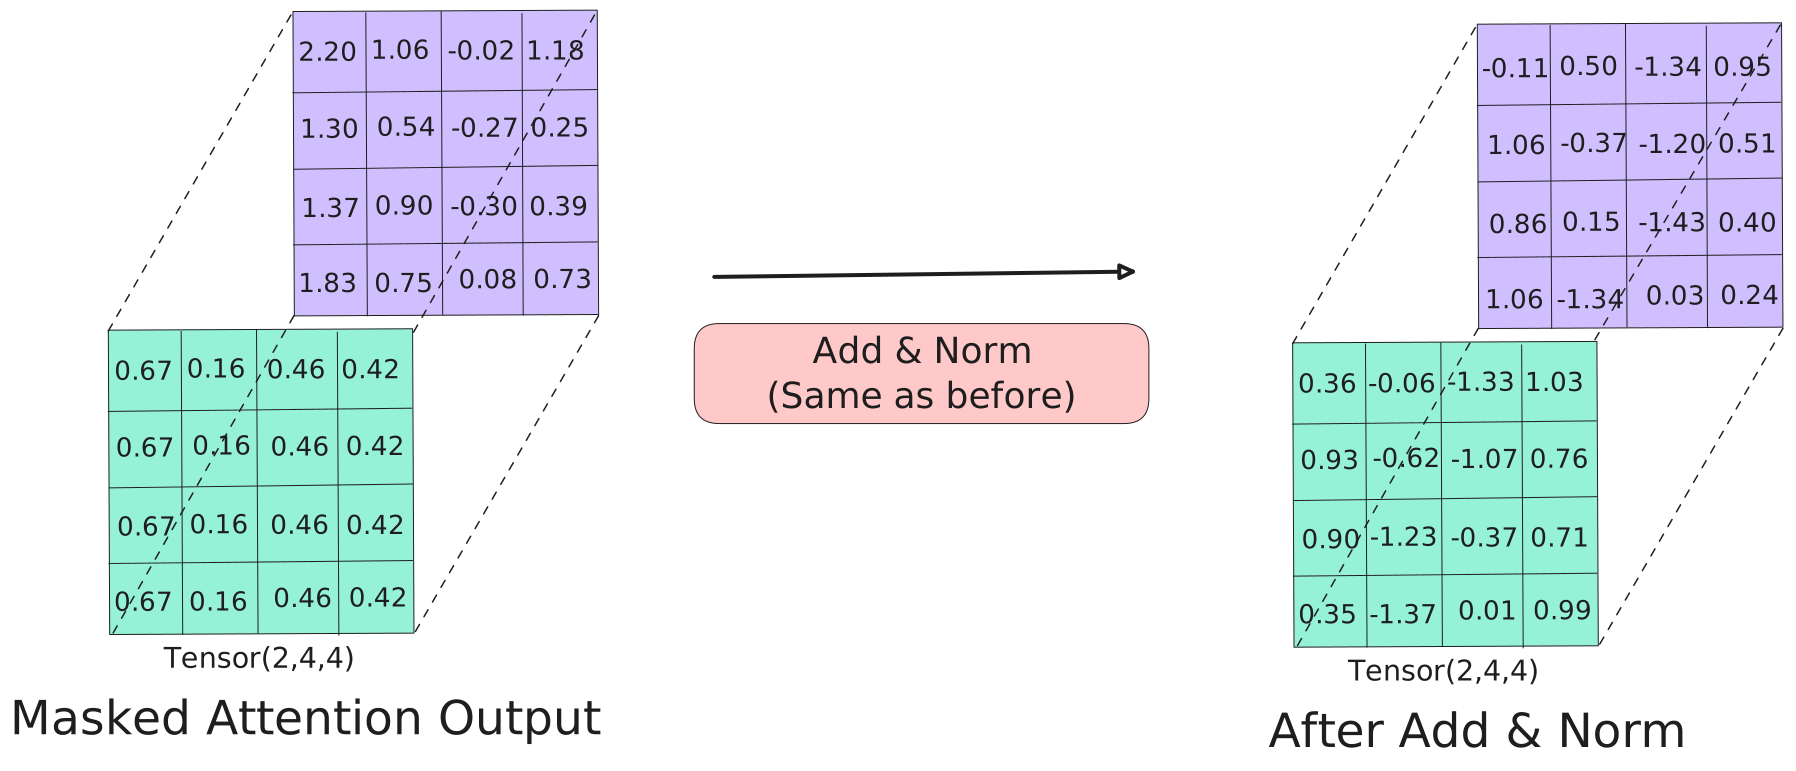
After Add & Norm · (2, 4, 4)
Q from decoder · K & V from encoder bridge between the two
09
Decoder: Cross-Attention
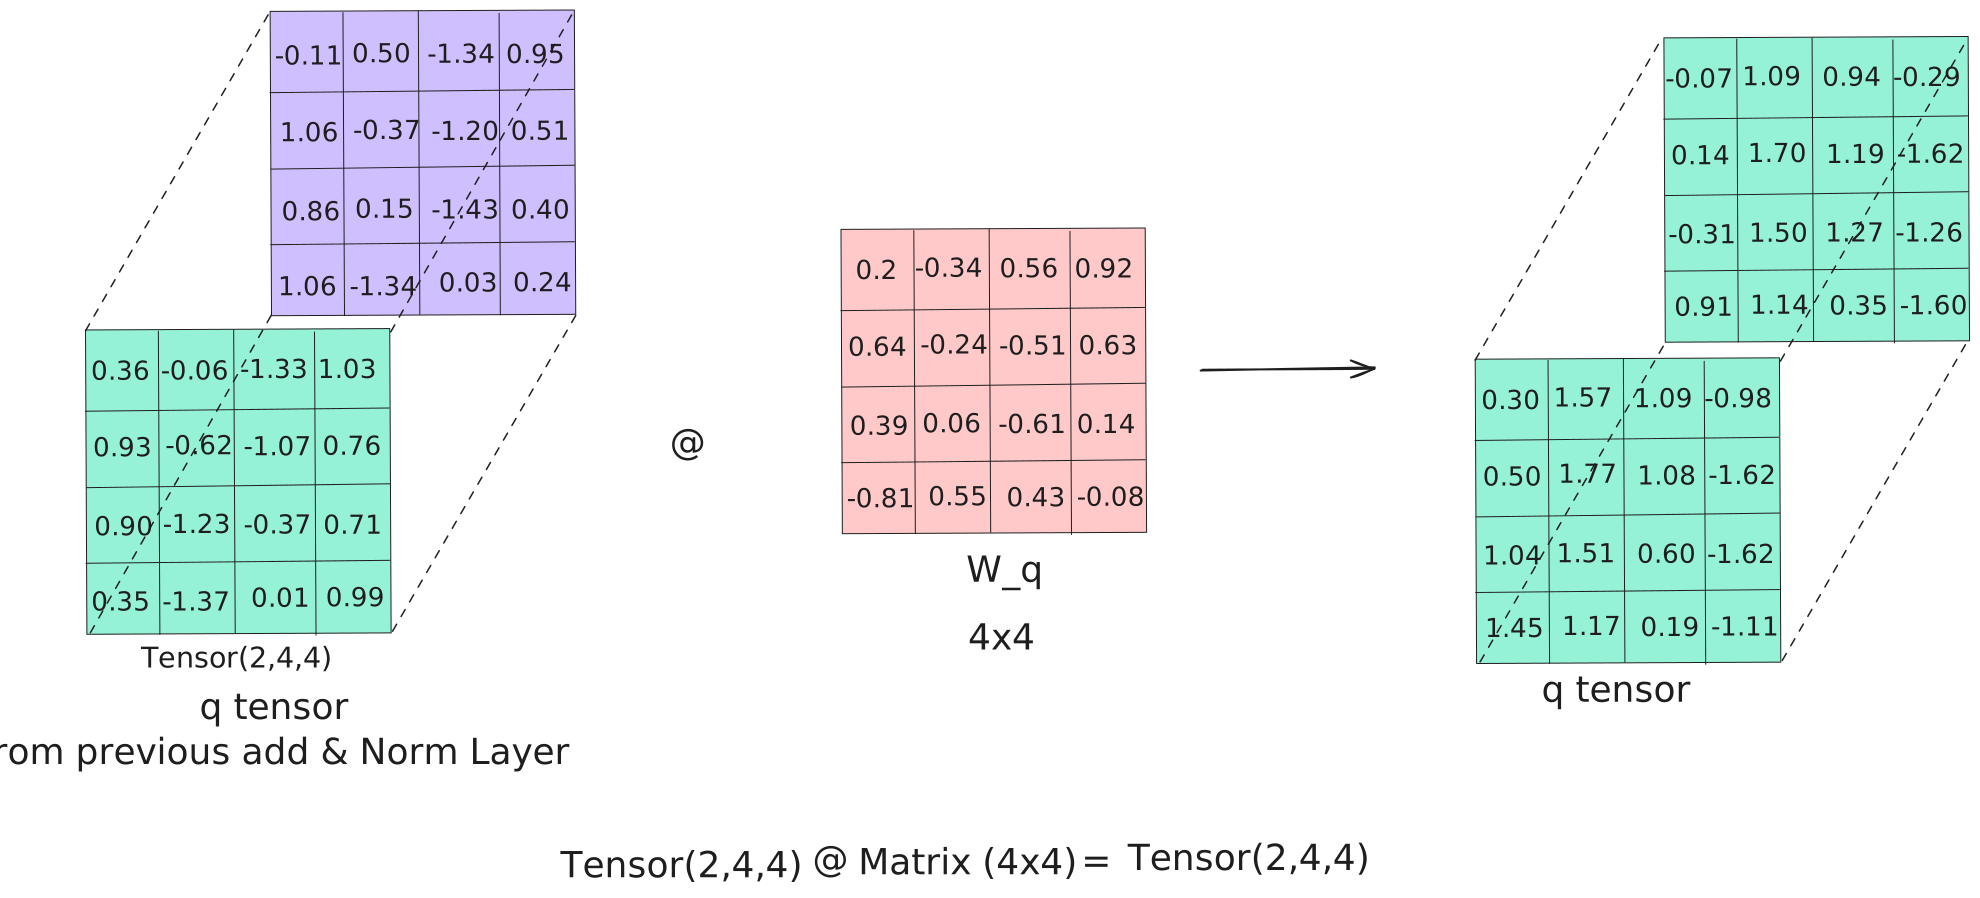
Q = decoder · W_Q.T
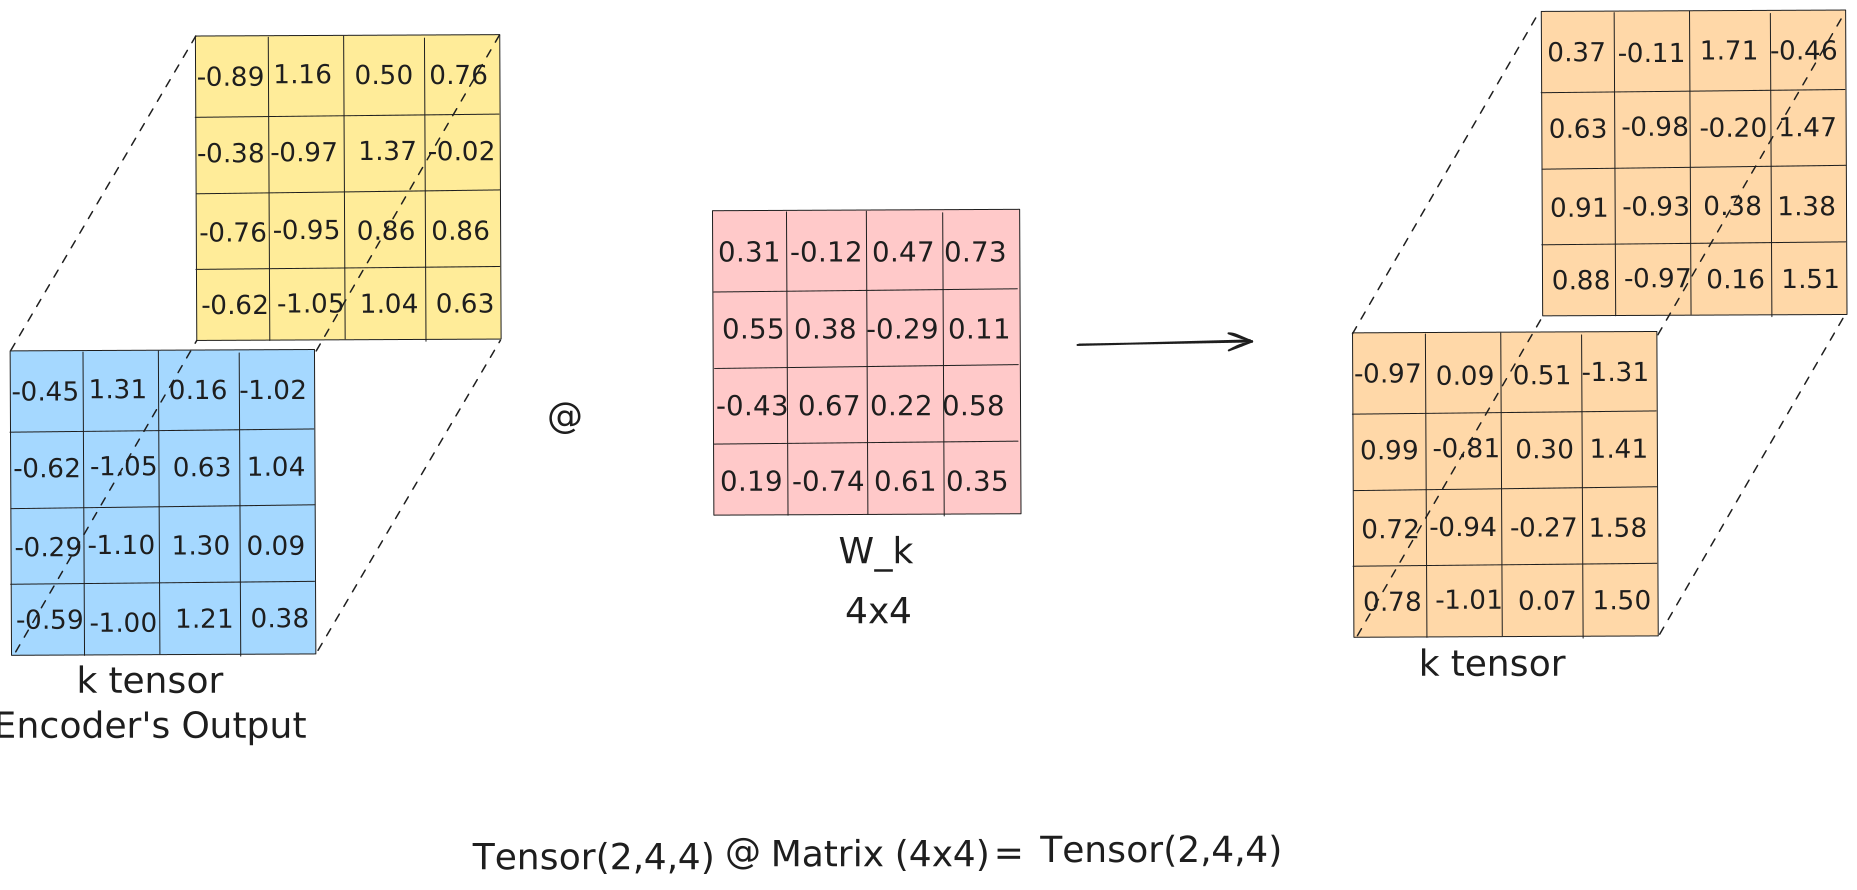
K = enc_out · W_K.T
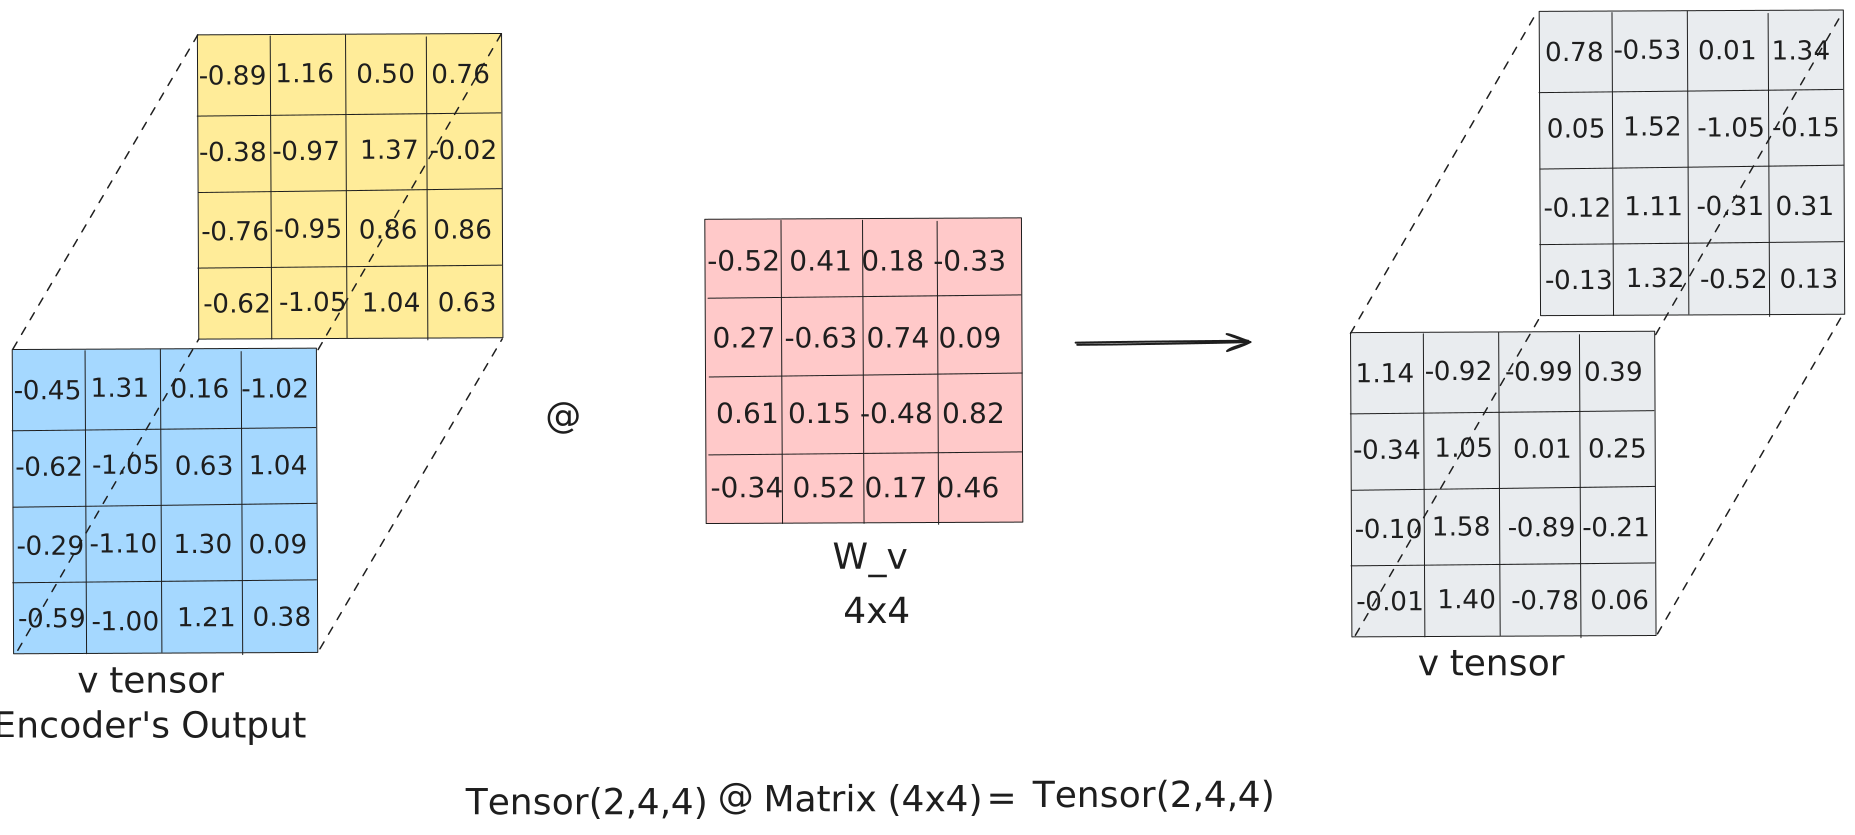
V = enc_out · W_V.T
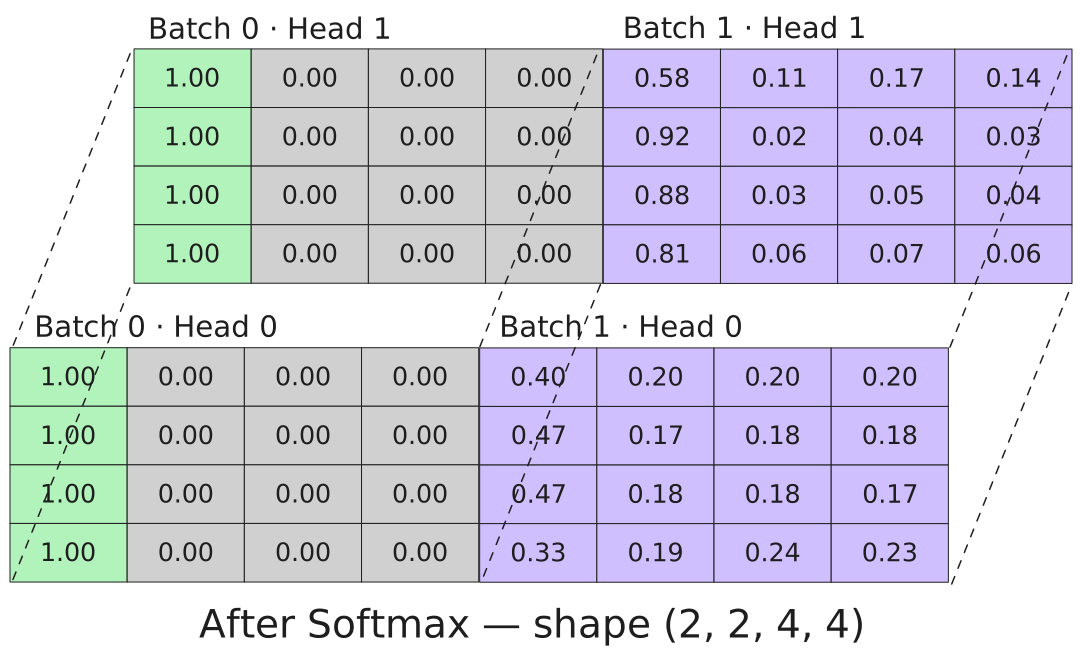
Cross-attn after softmax — no causal mask, PAD only · (2, 2, 4, 4)
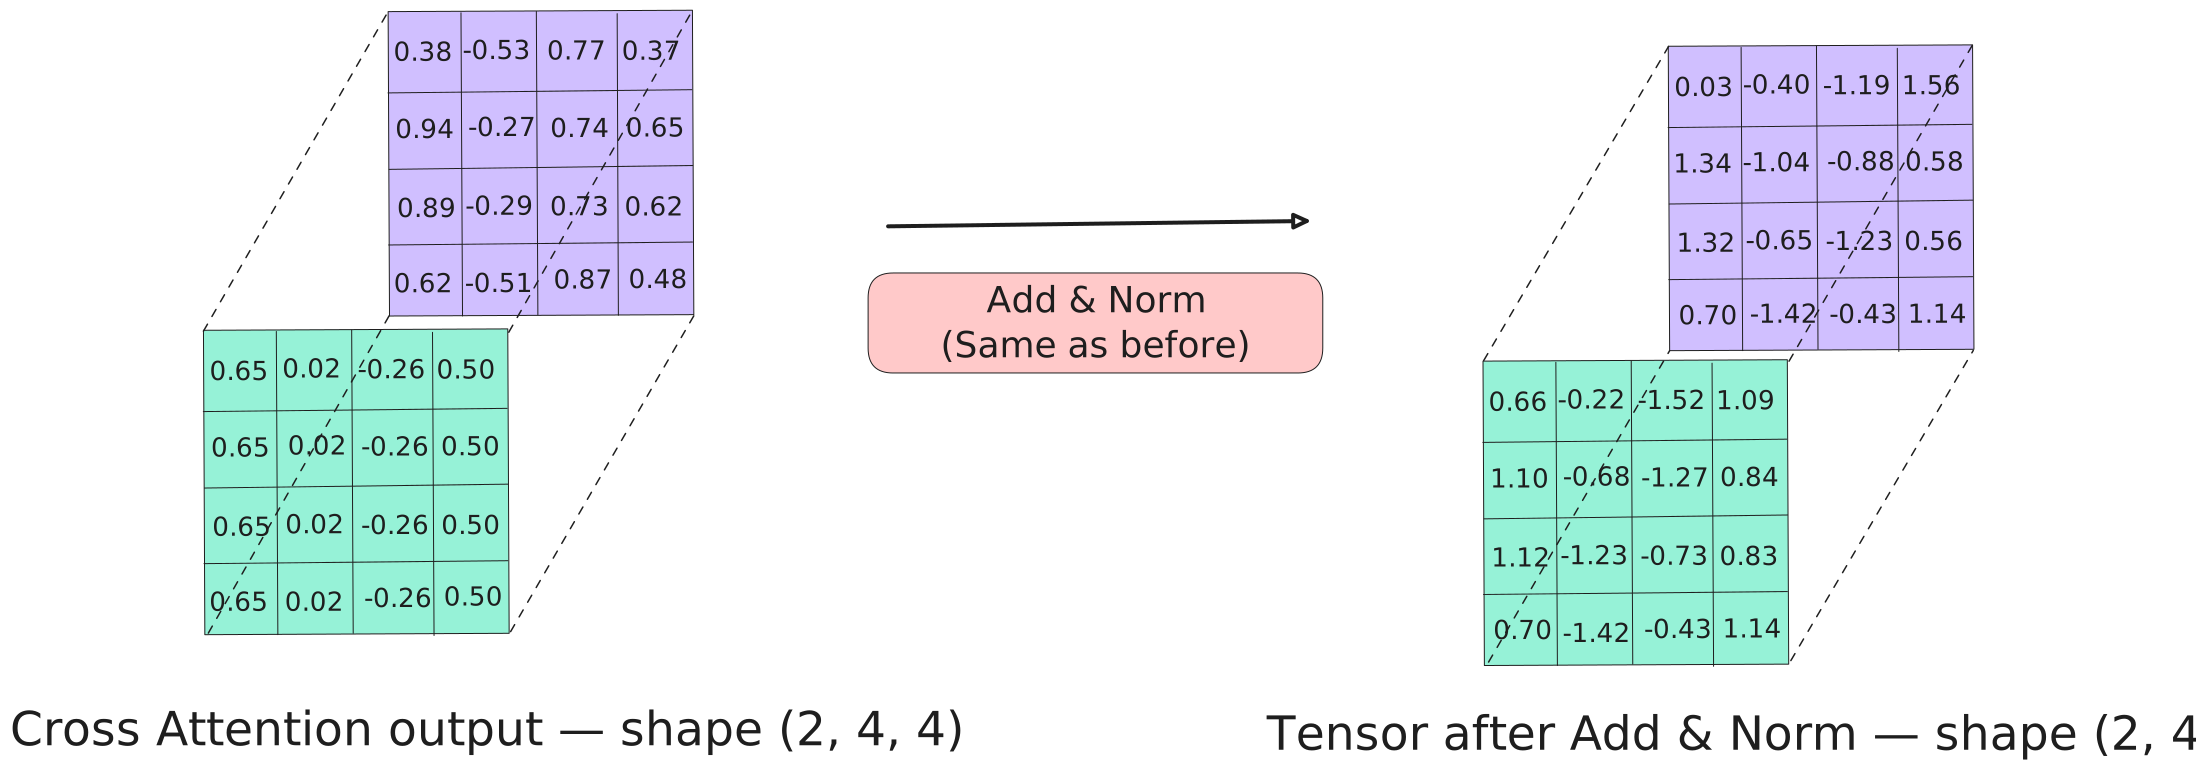
After Add & Norm · (2, 4, 4)
same FFN as encoder (2, 4, 4) → expand → compress → (2, 4, 4)
10
Decoder: FFN + Final Output
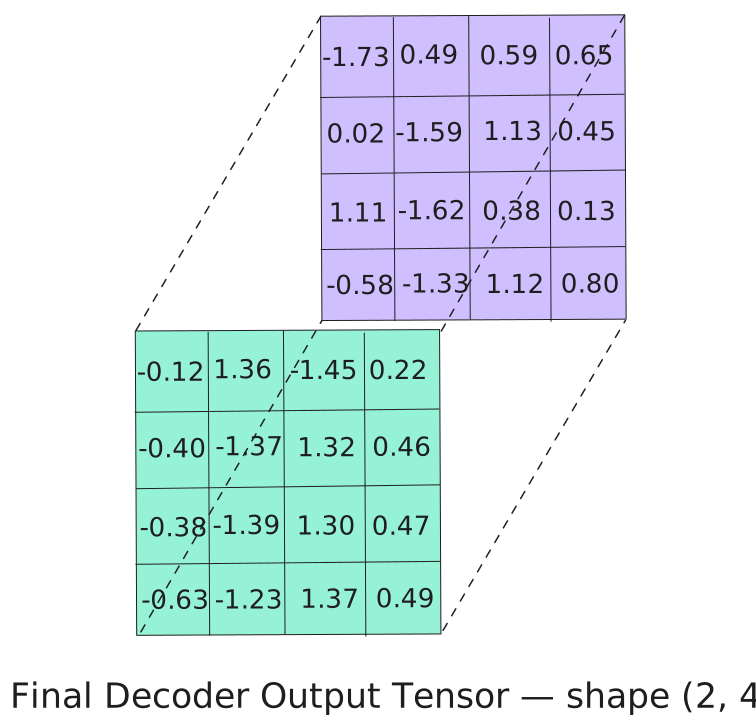
Final decoder output · (2, 4, 4)
Linear(4→14) + softmax (2, 4, 4) → (2, 4, 14)
11
Projection & Predictions
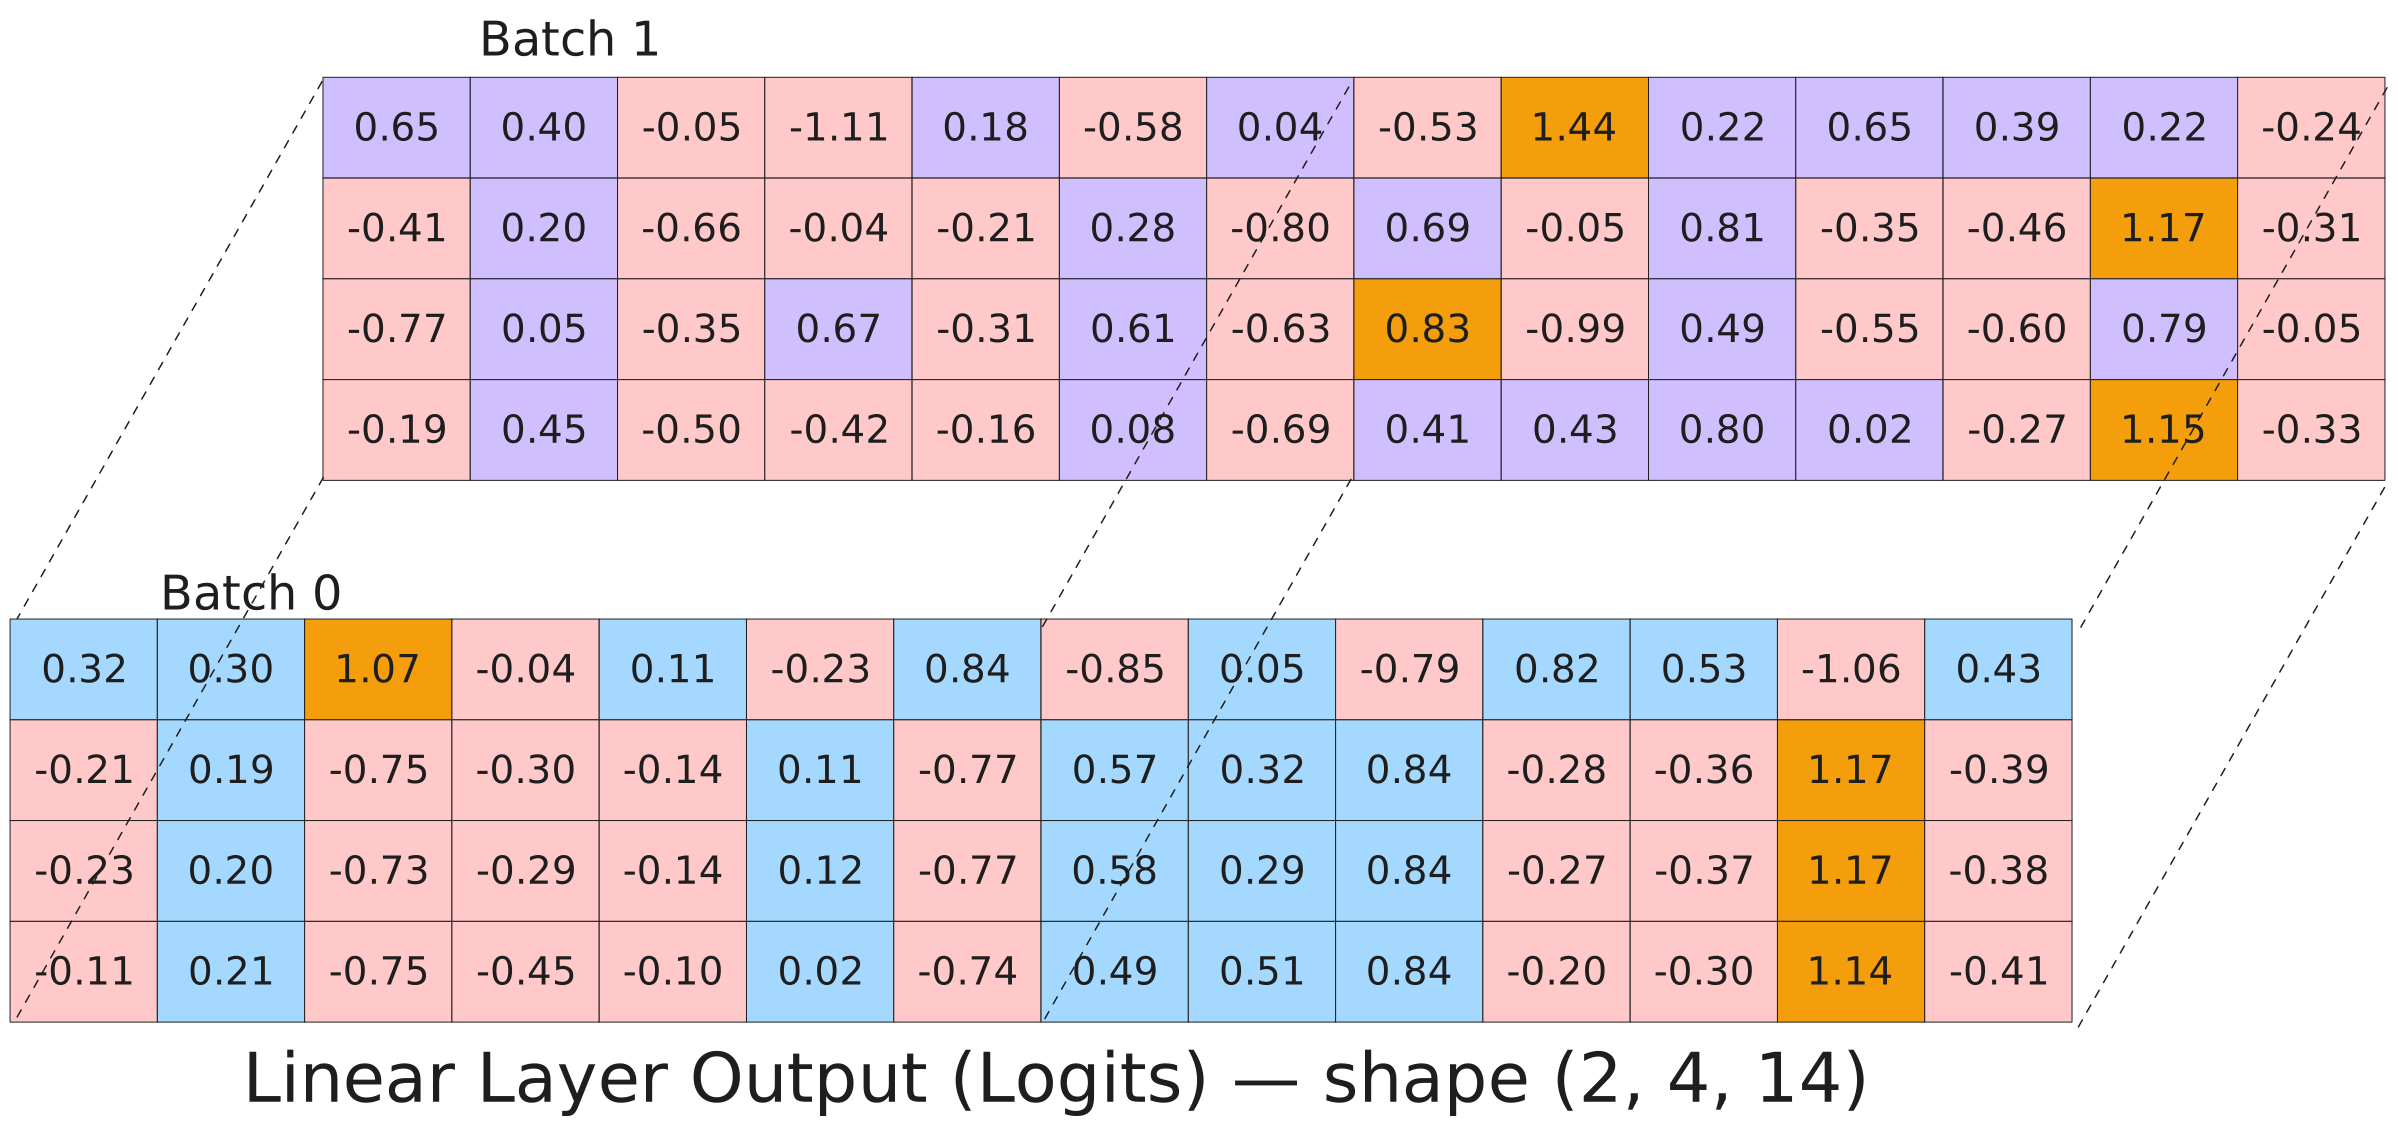
Linear(4→14) — one score per German word · (2, 4, 14)
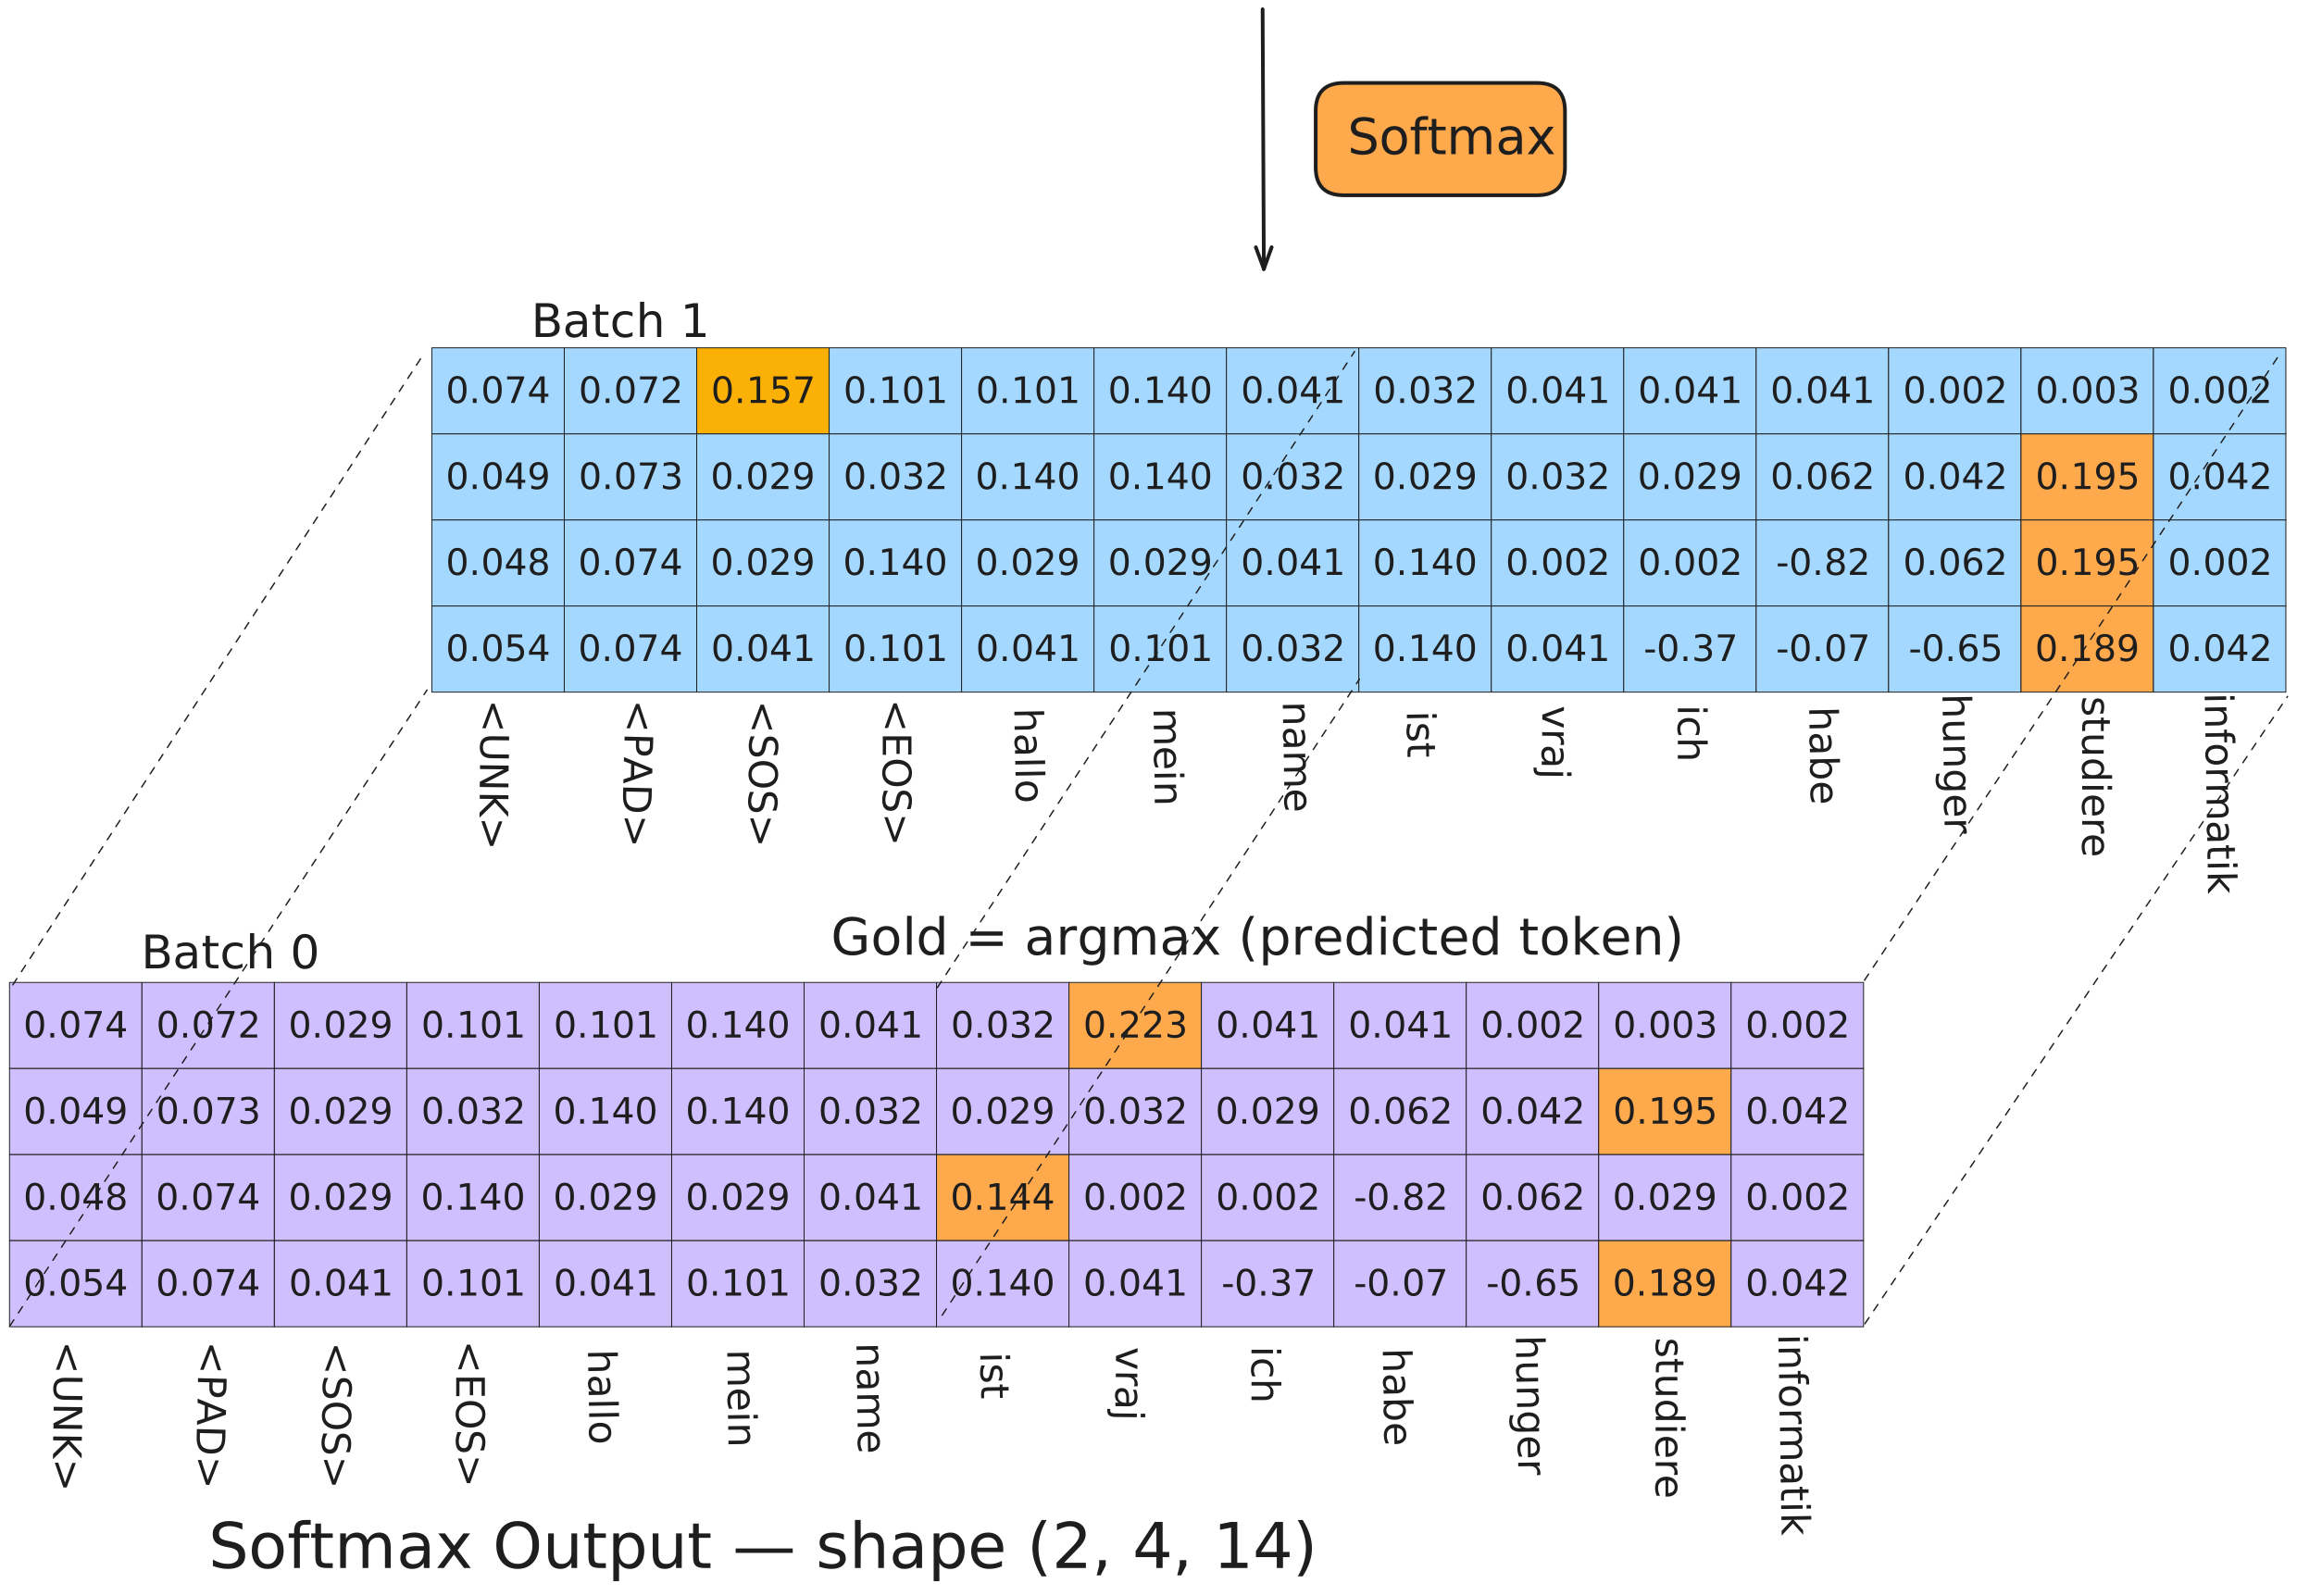
Softmax — each row a probability distribution over 14 tokens · (2, 4, 14)
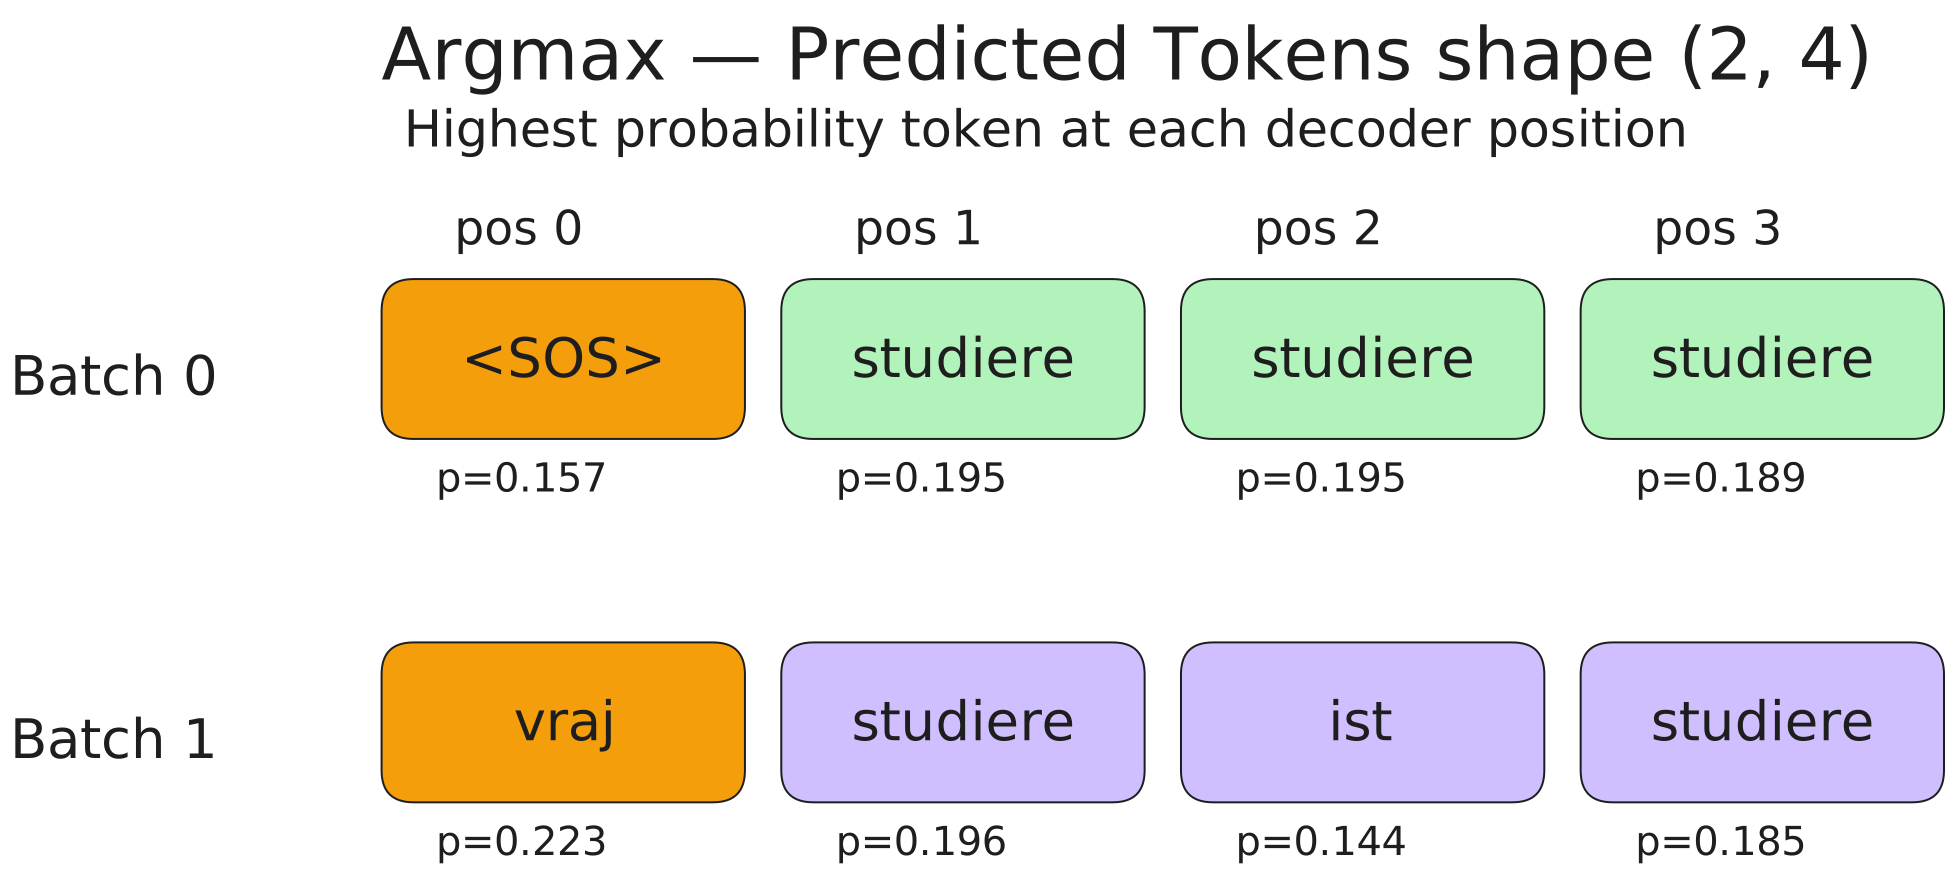
Argmax — predicted token IDs · (2, 4)
Input (2, 4) = Output (2, 4) · shape contract preserved